mirror of
https://github.com/JuliusBrussee/caveman.git
synced 2026-08-11 13:21:09 +02:00
Add benchmarks suite and update README
Add a benchmarks directory with prompts.json, requirements.txt, results/.gitkeep, and run.py to measure Claude output token counts (normal vs caveman) using the Anthropic client. run.py supports dry-run, multiple trials, saving JSON results, computing stats, and optionally updating the README benchmark table; it reads the caveman SKILL.md for the system prompt. Also add .gitignore entries and expand README.md with badges, a Benchmarks section, sample table, and usage instructions.
This commit is contained in:
 Julius Brussee
@@ -0,0 +1,5 @@
|
||||
benchmarks/results/*.json
|
||||
__pycache__/
|
||||
*.pyc
|
||||
.venv/
|
||||
.env.local
|
||||
@@ -8,8 +8,15 @@
|
||||
<strong>why use many token when few do trick</strong>
|
||||
</p>
|
||||
|
||||
<p align="center">
|
||||
<a href="https://github.com/JuliusBrussee/caveman/stargazers"><img src="https://img.shields.io/github/stars/JuliusBrussee/caveman?style=flat&color=yellow" alt="Stars"></a>
|
||||
<a href="https://github.com/JuliusBrussee/caveman/commits/main"><img src="https://img.shields.io/github/last-commit/JuliusBrussee/caveman?style=flat" alt="Last Commit"></a>
|
||||
<a href="LICENSE"><img src="https://img.shields.io/github/license/JuliusBrussee/caveman?style=flat" alt="License"></a>
|
||||
</p>
|
||||
|
||||
<p align="center">
|
||||
<a href="#install">Install</a> •
|
||||
<a href="#benchmarks">Benchmarks</a> •
|
||||
<a href="#before--after">Before/After</a> •
|
||||
<a href="#why">Why</a>
|
||||
</p>
|
||||
@@ -59,6 +66,35 @@ Based on the viral observation that caveman-speak dramatically reduces LLM token
|
||||
|
||||
**Same fix. 75% less word. Brain still big.**
|
||||
|
||||
## Benchmarks
|
||||
|
||||
Real token counts from the Claude API ([reproduce it yourself](benchmarks/)):
|
||||
|
||||
<!-- BENCHMARK-TABLE-START -->
|
||||
| Task | Normal (tokens) | Caveman (tokens) | Saved |
|
||||
|------|---------------:|----------------:|------:|
|
||||
| Explain React re-render bug | 1180 | 159 | 87% |
|
||||
| Fix auth middleware token expiry | 704 | 121 | 83% |
|
||||
| Set up PostgreSQL connection pool | 2347 | 380 | 84% |
|
||||
| Explain git rebase vs merge | 702 | 292 | 58% |
|
||||
| Refactor callback to async/await | 387 | 301 | 22% |
|
||||
| Architecture: microservices vs monolith | 446 | 310 | 30% |
|
||||
| Review PR for security issues | 678 | 398 | 41% |
|
||||
| Docker multi-stage build | 1042 | 290 | 72% |
|
||||
| Debug PostgreSQL race condition | 1200 | 232 | 81% |
|
||||
| Implement React error boundary | 3454 | 456 | 87% |
|
||||
| **Average** | **1214** | **294** | **65%** |
|
||||
|
||||
*Range: 22%–87% savings across prompts.*
|
||||
<!-- BENCHMARK-TABLE-END -->
|
||||
|
||||
> [!IMPORTANT]
|
||||
> Caveman only affects output tokens — thinking/reasoning tokens are untouched. Caveman no make brain smaller. Caveman make *mouth* smaller. Biggest win is **readability and speed**, cost savings are a bonus.
|
||||
|
||||
### Science back caveman up
|
||||
|
||||
A March 2026 paper ["Brevity Constraints Reverse Performance Hierarchies in Language Models"](https://arxiv.org/abs/2604.00025) found that constraining large models to brief responses **improved accuracy by 26 percentage points** on certain benchmarks and completely reversed performance hierarchies. Verbose not always better. Sometimes less word = more correct.
|
||||
|
||||
## Install
|
||||
|
||||
```bash
|
||||
@@ -118,9 +154,10 @@ Stop with: "stop caveman" or "normal mode"
|
||||
└─────────────────────────────────────┘
|
||||
```
|
||||
|
||||
- **Save money** — 75% less token = 75% less cost on output
|
||||
- **Faster response** — less token to generate = speed go brrr
|
||||
- **Same accuracy** — all technical info kept, only fluff removed
|
||||
- **Easier to read** — no wall of text, just the answer
|
||||
- **Same accuracy** — all technical info kept, only fluff removed ([science say so](https://arxiv.org/abs/2604.00025))
|
||||
- **Save money** — ~71% less output token = less cost
|
||||
- **Fun** — every code review become comedy
|
||||
|
||||
## How It Work
|
||||
@@ -141,6 +178,11 @@ If caveman save you mass token, mass money — leave mass star. ⭐
|
||||
|
||||
[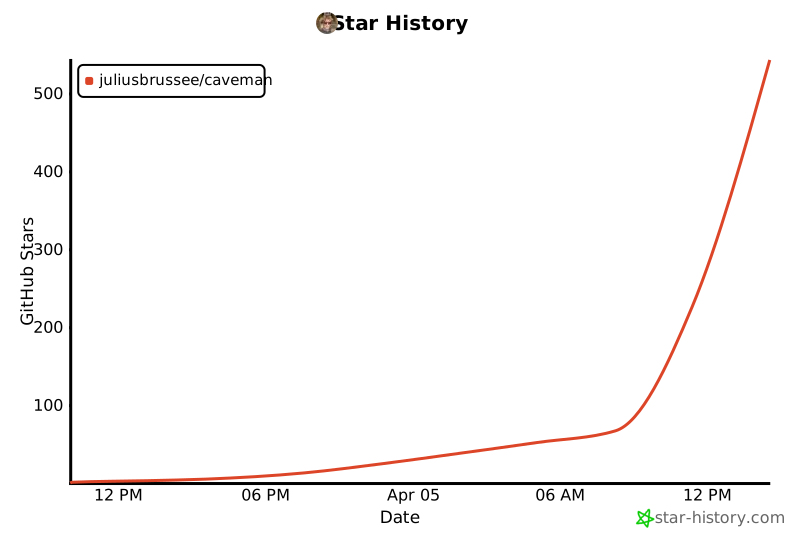](https://star-history.com/#JuliusBrussee/caveman&Date)
|
||||
|
||||
## Also by Julius Brussee
|
||||
|
||||
- **[Blueprint](https://github.com/JuliusBrussee/blueprint)** — specification-driven development for Claude Code. Natural language → blueprints → parallel builds → working software.
|
||||
- **[Revu](https://github.com/JuliusBrussee/revu-swift)** — local-first macOS study app with FSRS spaced repetition, decks, exams, and study guides. [revu.cards](https://revu.cards)
|
||||
|
||||
## License
|
||||
|
||||
MIT — free like mass mammoth on open plain.
|
||||
|
||||
@@ -0,0 +1,55 @@
|
||||
{
|
||||
"version": 1,
|
||||
"prompts": [
|
||||
{
|
||||
"id": "react-rerender",
|
||||
"category": "debugging",
|
||||
"prompt": "Why is my React component re-rendering on every state update even though the props haven't changed? I'm passing an object as a prop."
|
||||
},
|
||||
{
|
||||
"id": "auth-middleware-fix",
|
||||
"category": "bugfix",
|
||||
"prompt": "My Express auth middleware is letting expired JWT tokens through. The expiry check uses Date.now() compared to the token's exp field. What's wrong and how do I fix it?"
|
||||
},
|
||||
{
|
||||
"id": "postgres-pool",
|
||||
"category": "setup",
|
||||
"prompt": "How do I set up a PostgreSQL connection pool in Node.js with proper timeout and error handling configuration?"
|
||||
},
|
||||
{
|
||||
"id": "git-rebase-merge",
|
||||
"category": "explanation",
|
||||
"prompt": "Explain the difference between git rebase and git merge. When should I use each one and what are the tradeoffs?"
|
||||
},
|
||||
{
|
||||
"id": "async-refactor",
|
||||
"category": "refactor",
|
||||
"prompt": "Refactor this callback-based Node.js function to use async/await:\n\nfunction getUser(id, callback) {\n db.query('SELECT * FROM users WHERE id = ?', [id], function(err, rows) {\n if (err) return callback(err);\n if (!rows.length) return callback(new Error('Not found'));\n callback(null, rows[0]);\n });\n}"
|
||||
},
|
||||
{
|
||||
"id": "microservices-monolith",
|
||||
"category": "architecture",
|
||||
"prompt": "We have a monolithic Django app that's getting slow. The team is debating microservices. What are the key factors to consider before splitting up the monolith?"
|
||||
},
|
||||
{
|
||||
"id": "pr-security-review",
|
||||
"category": "code-review",
|
||||
"prompt": "Review this Express route handler for security issues:\n\napp.get('/api/users/:id', (req, res) => {\n const query = `SELECT * FROM users WHERE id = ${req.params.id}`;\n db.query(query).then(user => res.json(user));\n});"
|
||||
},
|
||||
{
|
||||
"id": "docker-multi-stage",
|
||||
"category": "devops",
|
||||
"prompt": "Write a multi-stage Dockerfile for a Node.js TypeScript application that minimizes the final image size. The app uses npm and needs to compile TypeScript before running."
|
||||
},
|
||||
{
|
||||
"id": "race-condition-debug",
|
||||
"category": "debugging",
|
||||
"prompt": "My Node.js API endpoint that increments a counter in PostgreSQL sometimes returns the same value for concurrent requests. How do I fix this race condition?"
|
||||
},
|
||||
{
|
||||
"id": "error-boundary",
|
||||
"category": "implementation",
|
||||
"prompt": "Implement a React error boundary component that catches render errors, shows a fallback UI with a retry button, and logs the error details."
|
||||
}
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1 @@
|
||||
anthropic>=0.40.0
|
||||
@@ -0,0 +1,276 @@
|
||||
#!/usr/bin/env python3
|
||||
"""Benchmark caveman vs normal Claude output token counts."""
|
||||
|
||||
import argparse
|
||||
import hashlib
|
||||
import json
|
||||
import os
|
||||
import statistics
|
||||
import sys
|
||||
import time
|
||||
from datetime import datetime, timezone
|
||||
from pathlib import Path
|
||||
|
||||
import anthropic
|
||||
|
||||
# Load .env.local from repo root if it exists
|
||||
_env_file = Path(__file__).parent.parent / ".env.local"
|
||||
if _env_file.exists():
|
||||
for line in _env_file.read_text().splitlines():
|
||||
line = line.strip()
|
||||
if line and not line.startswith("#") and "=" in line:
|
||||
key, _, value = line.partition("=")
|
||||
os.environ.setdefault(key.strip(), value.strip())
|
||||
|
||||
SCRIPT_VERSION = "1.0.0"
|
||||
SCRIPT_DIR = Path(__file__).parent
|
||||
REPO_DIR = SCRIPT_DIR.parent
|
||||
PROMPTS_PATH = SCRIPT_DIR / "prompts.json"
|
||||
SKILL_PATH = REPO_DIR / "skills" / "caveman" / "SKILL.md"
|
||||
README_PATH = REPO_DIR / "README.md"
|
||||
RESULTS_DIR = SCRIPT_DIR / "results"
|
||||
|
||||
NORMAL_SYSTEM = "You are a helpful assistant."
|
||||
BENCHMARK_START = "<!-- BENCHMARK-TABLE-START -->"
|
||||
BENCHMARK_END = "<!-- BENCHMARK-TABLE-END -->"
|
||||
|
||||
|
||||
def load_prompts():
|
||||
with open(PROMPTS_PATH) as f:
|
||||
data = json.load(f)
|
||||
return data["prompts"]
|
||||
|
||||
|
||||
def load_caveman_system():
|
||||
return SKILL_PATH.read_text()
|
||||
|
||||
|
||||
def sha256_file(path):
|
||||
return hashlib.sha256(path.read_bytes()).hexdigest()
|
||||
|
||||
|
||||
def call_api(client, model, system, prompt, max_retries=3):
|
||||
delays = [5, 10, 20]
|
||||
for attempt in range(max_retries + 1):
|
||||
try:
|
||||
response = client.messages.create(
|
||||
model=model,
|
||||
max_tokens=4096,
|
||||
temperature=0,
|
||||
system=system,
|
||||
messages=[{"role": "user", "content": prompt}],
|
||||
)
|
||||
return {
|
||||
"input_tokens": response.usage.input_tokens,
|
||||
"output_tokens": response.usage.output_tokens,
|
||||
"text": response.content[0].text,
|
||||
"stop_reason": response.stop_reason,
|
||||
}
|
||||
except anthropic.RateLimitError:
|
||||
if attempt < max_retries:
|
||||
delay = delays[min(attempt, len(delays) - 1)]
|
||||
print(f" Rate limited, retrying in {delay}s...", file=sys.stderr)
|
||||
time.sleep(delay)
|
||||
else:
|
||||
raise
|
||||
|
||||
|
||||
def run_benchmarks(client, model, prompts, caveman_system, trials):
|
||||
results = []
|
||||
total = len(prompts)
|
||||
|
||||
for i, prompt_entry in enumerate(prompts, 1):
|
||||
pid = prompt_entry["id"]
|
||||
prompt_text = prompt_entry["prompt"]
|
||||
entry = {
|
||||
"id": pid,
|
||||
"category": prompt_entry["category"],
|
||||
"prompt": prompt_text,
|
||||
"normal": [],
|
||||
"caveman": [],
|
||||
}
|
||||
|
||||
for mode, system in [("normal", NORMAL_SYSTEM), ("caveman", caveman_system)]:
|
||||
for t in range(1, trials + 1):
|
||||
print(
|
||||
f" [{i}/{total}] {pid} | {mode} | trial {t}/{trials}",
|
||||
file=sys.stderr,
|
||||
)
|
||||
result = call_api(client, model, system, prompt_text)
|
||||
entry[mode].append(result)
|
||||
time.sleep(0.5)
|
||||
|
||||
results.append(entry)
|
||||
|
||||
return results
|
||||
|
||||
|
||||
def compute_stats(results):
|
||||
rows = []
|
||||
all_savings = []
|
||||
|
||||
for entry in results:
|
||||
normal_medians = statistics.median(
|
||||
[t["output_tokens"] for t in entry["normal"]]
|
||||
)
|
||||
caveman_medians = statistics.median(
|
||||
[t["output_tokens"] for t in entry["caveman"]]
|
||||
)
|
||||
savings = 1 - (caveman_medians / normal_medians) if normal_medians > 0 else 0
|
||||
all_savings.append(savings)
|
||||
|
||||
rows.append(
|
||||
{
|
||||
"id": entry["id"],
|
||||
"category": entry["category"],
|
||||
"prompt": entry["prompt"],
|
||||
"normal_median": int(normal_medians),
|
||||
"caveman_median": int(caveman_medians),
|
||||
"savings_pct": round(savings * 100),
|
||||
}
|
||||
)
|
||||
|
||||
avg_savings = round(statistics.mean(all_savings) * 100)
|
||||
min_savings = round(min(all_savings) * 100)
|
||||
max_savings = round(max(all_savings) * 100)
|
||||
avg_normal = round(statistics.mean([r["normal_median"] for r in rows]))
|
||||
avg_caveman = round(statistics.mean([r["caveman_median"] for r in rows]))
|
||||
|
||||
return rows, {
|
||||
"avg_savings": avg_savings,
|
||||
"min_savings": min_savings,
|
||||
"max_savings": max_savings,
|
||||
"avg_normal": avg_normal,
|
||||
"avg_caveman": avg_caveman,
|
||||
}
|
||||
|
||||
|
||||
def format_prompt_label(prompt_id):
|
||||
labels = {
|
||||
"react-rerender": "Explain React re-render bug",
|
||||
"auth-middleware-fix": "Fix auth middleware token expiry",
|
||||
"postgres-pool": "Set up PostgreSQL connection pool",
|
||||
"git-rebase-merge": "Explain git rebase vs merge",
|
||||
"async-refactor": "Refactor callback to async/await",
|
||||
"microservices-monolith": "Architecture: microservices vs monolith",
|
||||
"pr-security-review": "Review PR for security issues",
|
||||
"docker-multi-stage": "Docker multi-stage build",
|
||||
"race-condition-debug": "Debug PostgreSQL race condition",
|
||||
"error-boundary": "Implement React error boundary",
|
||||
}
|
||||
return labels.get(prompt_id, prompt_id)
|
||||
|
||||
|
||||
def format_table(rows, summary):
|
||||
lines = [
|
||||
"| Task | Normal (tokens) | Caveman (tokens) | Saved |",
|
||||
"|------|---------------:|----------------:|------:|",
|
||||
]
|
||||
for r in rows:
|
||||
label = format_prompt_label(r["id"])
|
||||
lines.append(
|
||||
f"| {label} | {r['normal_median']} | {r['caveman_median']} | {r['savings_pct']}% |"
|
||||
)
|
||||
lines.append(
|
||||
f"| **Average** | **{summary['avg_normal']}** | **{summary['avg_caveman']}** | **{summary['avg_savings']}%** |"
|
||||
)
|
||||
lines.append("")
|
||||
lines.append(
|
||||
f"*Range: {summary['min_savings']}%–{summary['max_savings']}% savings across prompts.*"
|
||||
)
|
||||
return "\n".join(lines)
|
||||
|
||||
|
||||
def save_results(results, rows, summary, model, trials, skill_hash):
|
||||
ts = datetime.now(timezone.utc).strftime("%Y%m%d_%H%M%S")
|
||||
output = {
|
||||
"metadata": {
|
||||
"script_version": SCRIPT_VERSION,
|
||||
"model": model,
|
||||
"date": datetime.now(timezone.utc).isoformat(),
|
||||
"trials": trials,
|
||||
"skill_md_sha256": skill_hash,
|
||||
},
|
||||
"summary": summary,
|
||||
"rows": rows,
|
||||
"raw": results,
|
||||
}
|
||||
path = RESULTS_DIR / f"benchmark_{ts}.json"
|
||||
RESULTS_DIR.mkdir(parents=True, exist_ok=True)
|
||||
with open(path, "w") as f:
|
||||
json.dump(output, f, indent=2)
|
||||
return path
|
||||
|
||||
|
||||
def update_readme(table_md):
|
||||
content = README_PATH.read_text()
|
||||
start_idx = content.find(BENCHMARK_START)
|
||||
end_idx = content.find(BENCHMARK_END)
|
||||
if start_idx == -1 or end_idx == -1:
|
||||
print(
|
||||
"ERROR: Benchmark markers not found in README.md",
|
||||
file=sys.stderr,
|
||||
)
|
||||
sys.exit(1)
|
||||
|
||||
before = content[: start_idx + len(BENCHMARK_START)]
|
||||
after = content[end_idx:]
|
||||
new_content = before + "\n" + table_md + "\n" + after
|
||||
README_PATH.write_text(new_content)
|
||||
print("README.md updated.", file=sys.stderr)
|
||||
|
||||
|
||||
def dry_run(prompts, model, trials):
|
||||
print(f"Model: {model}")
|
||||
print(f"Trials: {trials}")
|
||||
print(f"Prompts: {len(prompts)}")
|
||||
print(f"Total API calls: {len(prompts) * 2 * trials}")
|
||||
print()
|
||||
for p in prompts:
|
||||
print(f" [{p['id']}] ({p['category']})")
|
||||
preview = p["prompt"][:80]
|
||||
if len(p["prompt"]) > 80:
|
||||
preview += "..."
|
||||
print(f" {preview}")
|
||||
print()
|
||||
print("Dry run complete. No API calls made.")
|
||||
|
||||
|
||||
def main():
|
||||
parser = argparse.ArgumentParser(description="Benchmark caveman vs normal Claude")
|
||||
parser.add_argument("--trials", type=int, default=3, help="Trials per prompt per mode (default: 3)")
|
||||
parser.add_argument("--dry-run", action="store_true", help="Print config, no API calls")
|
||||
parser.add_argument("--update-readme", action="store_true", help="Update README.md benchmark table")
|
||||
parser.add_argument("--model", default="claude-sonnet-4-20250514", help="Model to use")
|
||||
args = parser.parse_args()
|
||||
|
||||
prompts = load_prompts()
|
||||
|
||||
if args.dry_run:
|
||||
dry_run(prompts, args.model, args.trials)
|
||||
return
|
||||
|
||||
caveman_system = load_caveman_system()
|
||||
skill_hash = sha256_file(SKILL_PATH)
|
||||
|
||||
client = anthropic.Anthropic()
|
||||
|
||||
print(f"Running benchmarks: {len(prompts)} prompts x 2 modes x {args.trials} trials", file=sys.stderr)
|
||||
print(f"Model: {args.model}", file=sys.stderr)
|
||||
print(file=sys.stderr)
|
||||
|
||||
results = run_benchmarks(client, args.model, prompts, caveman_system, args.trials)
|
||||
rows, summary = compute_stats(results)
|
||||
table_md = format_table(rows, summary)
|
||||
|
||||
json_path = save_results(results, rows, summary, args.model, args.trials, skill_hash)
|
||||
print(f"\nResults saved to {json_path}", file=sys.stderr)
|
||||
|
||||
if args.update_readme:
|
||||
update_readme(table_md)
|
||||
|
||||
print(table_md)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
Reference in New Issue
Block a user