diff --git a/crates/sherpa-onnx-sys/README.md b/crates/sherpa-onnx-sys/README.md
index fbfe242be..14fa1e5f2 100644
--- a/crates/sherpa-onnx-sys/README.md
+++ b/crates/sherpa-onnx-sys/README.md
@@ -1,690 +1,51 @@
-
+# sherpa-onnx-sys for Buzz voice clients
-[](https://deepwiki.com/k2-fsa/sherpa-onnx)
+This package contains the crates.io `sherpa-onnx-sys` 1.13.4 FFI sources
+with a build script that supports caller-prepared mobile libraries. The
+bindings, package metadata, license, and `Cargo.toml.orig` preserve their
+upstream provenance.
-
+## Link modes
-Buzz carries the crates.io 1.13.4 FFI sources and locally patches the build
-script to link caller-prepared official iOS and Android libraries through
-`SHERPA_ONNX_LIB_DIR`. Desktop archive selection remains unchanged.
+`buzz-voice` exposes two mutually exclusive features:
+
+- `static` is the default and is used by desktop and iOS clients.
+- `shared` is used by Android clients.
+
+A shared consumer must disable the default static feature:
+
+```toml
+[target.'cfg(target_os = "android")'.dependencies]
+buzz-voice = { git = "https://github.com/block/buzz.git", rev = "", default-features = false, features = ["shared"] }
+
+[target.'cfg(target_os = "ios")'.dependencies]
+buzz-voice = { git = "https://github.com/block/buzz.git", rev = "", default-features = false, features = ["static"] }
+
+[patch.crates-io]
+sherpa-onnx-sys = { git = "https://github.com/block/buzz.git", rev = "" }
+```
+
+Cargo does not propagate `[patch.crates-io]` from dependencies, so the
+application workspace owns that patch.
+
+## Mobile native libraries
The application that produces the final native library owns archive download,
-checksum verification, slice selection, and packaging. It must select the
-`static` feature for iOS and the `shared` feature for Android. Because Cargo
-does not propagate `[patch.crates-io]` from dependencies, that application's
-workspace root must also patch `sherpa-onnx-sys` to this package.
-
+checksum verification, target-slice selection, and packaging.
`SHERPA_ONNX_LIB_DIR` points to the selected target's normalized link
-directory, not the root of the downloaded archive:
+directory:
-- iOS contains `libsherpa-onnx.a` and `libonnxruntime.a`. A consumer can
- extract the matching binaries from the official sherpa and ONNX Runtime
- XCFramework slices.
+- iOS contains `libsherpa-onnx.a` and `libonnxruntime.a`, extracted from
+ the matching official XCFramework slices.
- Android contains `libsherpa-onnx-c-api.so` and `libonnxruntime.so` from
the matching official ABI directory.
-The consumer remains responsible for embedding those libraries and the
-platform C++ runtime in its Xcode or Gradle product. Buzz Desktop's independent
-Tauri workspace is a desktop consumer and does not select these mobile modes.
+The consumer embeds these libraries and the platform C++ runtime in its Xcode
+or Gradle product. Mobile builds fail closed when
+`SHERPA_ONNX_LIB_DIR` is missing or invalid. Supported desktop targets select
+and download the matching official archive when a caller does not provide a
+library directory.
- ### Supported functions
+Upstream project:
-|Speech recognition| [Speech synthesis][tts-url] | [Source separation][ss-url] |
-|------------------|------------------|-------------------|
-| ✔️ | ✔️ | ✔️ |
-
-|Speaker identification| [Speaker diarization][sd-url] | Speaker verification |
-|----------------------|-------------------- |------------------------|
-| ✔️ | ✔️ | ✔️ |
-
-| [Spoken Language identification][slid-url] | [Audio tagging][at-url] | [Voice activity detection][vad-url] |
-|--------------------------------|---------------|--------------------------|
-| ✔️ | ✔️ | ✔️ |
-
-| [Keyword spotting][kws-url] | [Add punctuation][punct-url] | [Speech enhancement][se-url] |
-|------------------|-----------------|--------------------|
-| ✔️ | ✔️ | ✔️ |
-
-
-### Supported platforms
-
-|Architecture| Android | iOS | Windows | macOS | linux | HarmonyOS |
-|------------|---------|---------|------------|-------|-------|-----------|
-| x64 | ✔️ | | ✔️ | ✔️ | ✔️ | ✔️ |
-| x86 | ✔️ | | ✔️ | | | |
-| arm64 | ✔️ | ✔️ | ✔️ | ✔️ | ✔️ | ✔️ |
-| arm32 | ✔️ | | | | ✔️ | ✔️ |
-| riscv64 | | | | | ✔️ | |
-
-### Supported programming languages
-
-| 1. C++ | 2. C | 3. Python | 4. JavaScript |
-|--------|-------|-----------|---------------|
-| ✔️ | ✔️ | ✔️ | ✔️ |
-
-|5. Java | 6. C# | 7. Kotlin | 8. Swift |
-|--------|-------|-----------|----------|
-| ✔️ | ✔️ | ✔️ | ✔️ |
-
-| 9. Go | 10. Dart | 11. Rust | 12. Pascal |
-|-------|----------|----------|------------|
-| ✔️ | ✔️ | ✔️ | ✔️ |
-
-
-It also supports WebAssembly.
-
-### Supported NPUs
-
-| [1. Rockchip NPU (RKNN)][rknpu-doc] | [2. Qualcomm NPU (QNN)][qnn-doc] | [3. Ascend NPU][ascend-doc] |
-|-------------------------------------|-----------------------------------|-----------------------------|
-| ✔️ | ✔️ | ✔️ |
-
-| [4. Axera NPU][axera-npu] |
-|---------------------------|
-| ✔️ |
-
-[Join our discord](https://discord.gg/fJdxzg2VbG)
-
-
-## Introduction
-
-This repository supports running the following functions **locally**
-
- - Speech-to-text (i.e., ASR); both streaming and non-streaming are supported
- - Text-to-speech (i.e., TTS)
- - Speaker diarization
- - Speaker identification
- - Speaker verification
- - Spoken language identification
- - Audio tagging
- - VAD (e.g., [silero-vad][silero-vad])
- - Speech enhancement (e.g., [gtcrn][gtcrn], [DPDFNet](https://github.com/ceva-ip/DPDFNet))
- - Keyword spotting
- - Source separation (e.g., [spleeter][spleeter], [UVR][UVR])
-
-on the following platforms and operating systems:
-
- - x86, ``x86_64``, 32-bit ARM, 64-bit ARM (arm64, aarch64), RISC-V (riscv64), **RK NPU**, **Ascend NPU**
- - Linux, macOS, Windows, openKylin
- - Android, WearOS
- - iOS
- - HarmonyOS
- - NodeJS
- - WebAssembly
- - [NVIDIA Jetson Orin NX][NVIDIA Jetson Orin NX] (Support running on both CPU and GPU)
- - [NVIDIA Jetson Nano B01][NVIDIA Jetson Nano B01] (Support running on both CPU and GPU)
- - [Raspberry Pi][Raspberry Pi]
- - [RV1126][RV1126]
- - [LicheePi4A][LicheePi4A]
- - [VisionFive 2][VisionFive 2]
- - [旭日X3派][旭日X3派]
- - [爱芯派][爱芯派]
- - [RK3588][RK3588]
- - [SpacemiT-K1][SpacemiT-K1]
- - [SpacemiT-K3][SpacemiT-K3]
- - etc
-
-with the following APIs
-
- - C++, C, Python, Go, ``C#``
- - Java, Kotlin, JavaScript
- - Swift, Rust
- - Dart, Object Pascal
-
-### Links for Huggingface Spaces
-
-
-You can visit the following Huggingface spaces to try sherpa-onnx without
-installing anything. All you need is a browser.
-
-| Description | URL | 中国镜像 |
-|-------------------------------------------------------|-----------------------------------------|----------------------------------------|
-| Speaker diarization | [Click me][hf-space-speaker-diarization]| [镜像][hf-space-speaker-diarization-cn]|
-| Speech recognition | [Click me][hf-space-asr] | [镜像][hf-space-asr-cn] |
-| Speech recognition with [Whisper][Whisper] | [Click me][hf-space-asr-whisper] | [镜像][hf-space-asr-whisper-cn] |
-| Speech synthesis | [Click me][hf-space-tts] | [镜像][hf-space-tts-cn] |
-| Generate subtitles | [Click me][hf-space-subtitle] | [镜像][hf-space-subtitle-cn] |
-| Audio tagging | [Click me][hf-space-audio-tagging] | [镜像][hf-space-audio-tagging-cn] |
-| Source separation | [Click me][hf-space-source-separation] | [镜像][hf-space-source-separation-cn] |
-| Spoken language identification with [Whisper][Whisper]| [Click me][hf-space-slid-whisper] | [镜像][hf-space-slid-whisper-cn] |
-
-We also have spaces built using WebAssembly. They are listed below:
-
-| Description | Huggingface space| ModelScope space|
-|------------------------------------------------------------------------------------------|------------------|-----------------|
-|Voice activity detection with [silero-vad][silero-vad] | [Click me][wasm-hf-vad]|[地址][wasm-ms-vad]|
-|Real-time speech recognition (Chinese + English) with Zipformer | [Click me][wasm-hf-streaming-asr-zh-en-zipformer]|[地址][wasm-hf-streaming-asr-zh-en-zipformer]|
-|Real-time speech recognition (Chinese + English) with Paraformer |[Click me][wasm-hf-streaming-asr-zh-en-paraformer]| [地址][wasm-ms-streaming-asr-zh-en-paraformer]|
-|Real-time speech recognition (Chinese + English + Cantonese) with [Paraformer-large][Paraformer-large]|[Click me][wasm-hf-streaming-asr-zh-en-yue-paraformer]| [地址][wasm-ms-streaming-asr-zh-en-yue-paraformer]|
-|Real-time speech recognition (English) |[Click me][wasm-hf-streaming-asr-en-zipformer] |[地址][wasm-ms-streaming-asr-en-zipformer]|
-|VAD + speech recognition (Chinese) with [Zipformer CTC](https://k2-fsa.github.io/sherpa/onnx/pretrained_models/offline-ctc/icefall/zipformer.html#sherpa-onnx-zipformer-ctc-zh-int8-2025-07-03-chinese)|[Click me][wasm-hf-vad-asr-zh-zipformer-ctc-07-03]| [地址][wasm-ms-vad-asr-zh-zipformer-ctc-07-03]|
-|VAD + speech recognition (Chinese + English + Korean + Japanese + Cantonese) with [SenseVoice][SenseVoice]|[Click me][wasm-hf-vad-asr-zh-en-ko-ja-yue-sense-voice]| [地址][wasm-ms-vad-asr-zh-en-ko-ja-yue-sense-voice]|
-|VAD + speech recognition (English) with [Whisper][Whisper] tiny.en|[Click me][wasm-hf-vad-asr-en-whisper-tiny-en]| [地址][wasm-ms-vad-asr-en-whisper-tiny-en]|
-|VAD + speech recognition (English) with [Moonshine tiny][Moonshine tiny]|[Click me][wasm-hf-vad-asr-en-moonshine-tiny-en]| [地址][wasm-ms-vad-asr-en-moonshine-tiny-en]|
-|VAD + speech recognition (English) with Zipformer trained with [GigaSpeech][GigaSpeech] |[Click me][wasm-hf-vad-asr-en-zipformer-gigaspeech]| [地址][wasm-ms-vad-asr-en-zipformer-gigaspeech]|
-|VAD + speech recognition (Chinese) with Zipformer trained with [WenetSpeech][WenetSpeech] |[Click me][wasm-hf-vad-asr-zh-zipformer-wenetspeech]| [地址][wasm-ms-vad-asr-zh-zipformer-wenetspeech]|
-|VAD + speech recognition (Japanese) with Zipformer trained with [ReazonSpeech][ReazonSpeech]|[Click me][wasm-hf-vad-asr-ja-zipformer-reazonspeech]| [地址][wasm-ms-vad-asr-ja-zipformer-reazonspeech]|
-|VAD + speech recognition (Thai) with Zipformer trained with [GigaSpeech2][GigaSpeech2] |[Click me][wasm-hf-vad-asr-th-zipformer-gigaspeech2]| [地址][wasm-ms-vad-asr-th-zipformer-gigaspeech2]|
-|VAD + speech recognition (Chinese 多种方言) with a [TeleSpeech-ASR][TeleSpeech-ASR] CTC model|[Click me][wasm-hf-vad-asr-zh-telespeech]| [地址][wasm-ms-vad-asr-zh-telespeech]|
-|VAD + speech recognition (English + Chinese, 及多种中文方言) with Paraformer-large |[Click me][wasm-hf-vad-asr-zh-en-paraformer-large]| [地址][wasm-ms-vad-asr-zh-en-paraformer-large]|
-|VAD + speech recognition (English + Chinese, 及多种中文方言) with Paraformer-small |[Click me][wasm-hf-vad-asr-zh-en-paraformer-small]| [地址][wasm-ms-vad-asr-zh-en-paraformer-small]|
-|VAD + speech recognition (多语种及多种中文方言) with [Dolphin][Dolphin]-base |[Click me][wasm-hf-vad-asr-multi-lang-dolphin-base]| [地址][wasm-ms-vad-asr-multi-lang-dolphin-base]|
-|Speech synthesis (Piper, English) |[Click me][wasm-hf-tts-piper-en]| [地址][wasm-ms-tts-piper-en]|
-|Speech synthesis (Piper, German) |[Click me][wasm-hf-tts-piper-de]| [地址][wasm-ms-tts-piper-de]|
-|Speech synthesis (Matcha, Chinese) |[Click me][wasm-hf-tts-matcha-zh]| [地址][wasm-ms-tts-matcha-zh]|
-|Speech synthesis (Matcha, English) |[Click me][wasm-hf-tts-matcha-en]| [地址][wasm-ms-tts-matcha-en]|
-|Speech synthesis (Matcha, Chinese+English) |[Click me][wasm-hf-tts-matcha-zh-en]| [地址][wasm-ms-tts-matcha-zh-en]|
-|Speaker diarization |[Click me][wasm-hf-speaker-diarization]|[地址][wasm-ms-speaker-diarization]|
-|Voice cloning with ZipVoice (Chinese+English) |[Click me][wasm-hf-voice-cloning-zipvoice]|[地址][wasm-ms-voice-cloning-zipvoice]|
-|Voice cloning with Pocket TTS (English) |[Click me][wasm-hf-voice-cloning-pocket]|[地址][wasm-ms-voice-cloning-pocket]|
-
-
-
-### Links for pre-built Android APKs
-
-
-
-You can find pre-built Android APKs for this repository in the following table
-
-| Description | URL | 中国用户 |
-|----------------------------------------|------------------------------------|-----------------------------------|
-| Speaker diarization | [Address][apk-speaker-diarization] | [点此][apk-speaker-diarization-cn]|
-| Streaming speech recognition | [Address][apk-streaming-asr] | [点此][apk-streaming-asr-cn] |
-| Simulated-streaming speech recognition | [Address][apk-simula-streaming-asr]| [点此][apk-simula-streaming-asr-cn]|
-| Text-to-speech | [Address][apk-tts] | [点此][apk-tts-cn] |
-| Voice activity detection (VAD) | [Address][apk-vad] | [点此][apk-vad-cn] |
-| VAD + non-streaming speech recognition | [Address][apk-vad-asr] | [点此][apk-vad-asr-cn] |
-| Two-pass speech recognition | [Address][apk-2pass] | [点此][apk-2pass-cn] |
-| Audio tagging | [Address][apk-at] | [点此][apk-at-cn] |
-| Audio tagging (WearOS) | [Address][apk-at-wearos] | [点此][apk-at-wearos-cn] |
-| Speaker identification | [Address][apk-sid] | [点此][apk-sid-cn] |
-| Spoken language identification | [Address][apk-slid] | [点此][apk-slid-cn] |
-| Keyword spotting | [Address][apk-kws] | [点此][apk-kws-cn] |
-
-
-
-### Links for pre-built Flutter APPs
-
-
-
-#### Real-time speech recognition
-
-| Description | URL | 中国用户 |
-|--------------------------------|-------------------------------------|-------------------------------------|
-| Streaming speech recognition | [Address][apk-flutter-streaming-asr]| [点此][apk-flutter-streaming-asr-cn]|
-
-#### Text-to-speech
-
-| Description | URL | 中国用户 |
-|------------------------------------------|------------------------------------|------------------------------------|
-| Android (arm64-v8a, armeabi-v7a, x86_64) | [Address][flutter-tts-android] | [点此][flutter-tts-android-cn] |
-| Linux (x64) | [Address][flutter-tts-linux] | [点此][flutter-tts-linux-cn] |
-| macOS (x64) | [Address][flutter-tts-macos-x64] | [点此][flutter-tts-macos-x64-cn] |
-| macOS (arm64) | [Address][flutter-tts-macos-arm64] | [点此][flutter-tts-macos-arm64-cn] |
-| Windows (x64) | [Address][flutter-tts-win-x64] | [点此][flutter-tts-win-x64-cn] |
-
-> Note: You need to build from source for iOS.
-
-
-
-### Links for pre-built Lazarus APPs
-
-
-
-#### Generating subtitles
-
-| Description | URL | 中国用户 |
-|--------------------------------|----------------------------|----------------------------|
-| Generate subtitles (生成字幕) | [Address][lazarus-subtitle]| [点此][lazarus-subtitle-cn]|
-
-
-
-### Links for pre-trained models
-
-
-
-| Description | URL |
-|---------------------------------------------|---------------------------------------------------------------------------------------|
-| Speech recognition (speech to text, ASR) | [Address][asr-models] |
-| Text-to-speech (TTS) | [Address][tts-models] |
-| VAD | [Address][vad-models] |
-| Keyword spotting | [Address][kws-models] |
-| Audio tagging | [Address][at-models] |
-| Speaker identification (Speaker ID) | [Address][sid-models] |
-| Spoken language identification (Language ID)| See multi-lingual [Whisper][Whisper] ASR models from [Speech recognition][asr-models]|
-| Punctuation | [Address][punct-models] |
-| Speaker segmentation | [Address][speaker-segmentation-models] |
-| Speech enhancement | [Address][speech-enhancement-models] |
-| Source separation | [Address][source-separation-models] |
-
-
-
-#### Some pre-trained ASR models (Streaming)
-
-
-
-Please see
-
- -
- -
- -
-
-for more models. The following table lists only **SOME** of them.
-
-
-|Name | Supported Languages| Description|
-|-----|-----|----|
-|[sherpa-onnx-streaming-zipformer-bilingual-zh-en-2023-02-20][sherpa-onnx-streaming-zipformer-bilingual-zh-en-2023-02-20]| Chinese, English| See [also](https://k2-fsa.github.io/sherpa/onnx/pretrained_models/online-transducer/zipformer-transducer-models.html#csukuangfj-sherpa-onnx-streaming-zipformer-bilingual-zh-en-2023-02-20-bilingual-chinese-english)|
-|[sherpa-onnx-streaming-zipformer-small-bilingual-zh-en-2023-02-16][sherpa-onnx-streaming-zipformer-small-bilingual-zh-en-2023-02-16]| Chinese, English| See [also](https://k2-fsa.github.io/sherpa/onnx/pretrained_models/online-transducer/zipformer-transducer-models.html#sherpa-onnx-streaming-zipformer-small-bilingual-zh-en-2023-02-16-bilingual-chinese-english)|
-|[sherpa-onnx-streaming-zipformer-zh-14M-2023-02-23][sherpa-onnx-streaming-zipformer-zh-14M-2023-02-23]|Chinese| Suitable for Cortex A7 CPU. See [also](https://k2-fsa.github.io/sherpa/onnx/pretrained_models/online-transducer/zipformer-transducer-models.html#sherpa-onnx-streaming-zipformer-zh-14m-2023-02-23)|
-|[sherpa-onnx-streaming-zipformer-en-20M-2023-02-17][sherpa-onnx-streaming-zipformer-en-20M-2023-02-17]|English|Suitable for Cortex A7 CPU. See [also](https://k2-fsa.github.io/sherpa/onnx/pretrained_models/online-transducer/zipformer-transducer-models.html#sherpa-onnx-streaming-zipformer-en-20m-2023-02-17)|
-|[sherpa-onnx-streaming-zipformer-korean-2024-06-16][sherpa-onnx-streaming-zipformer-korean-2024-06-16]|Korean| See [also](https://k2-fsa.github.io/sherpa/onnx/pretrained_models/online-transducer/zipformer-transducer-models.html#sherpa-onnx-streaming-zipformer-korean-2024-06-16-korean)|
-|[sherpa-onnx-streaming-zipformer-fr-2023-04-14][sherpa-onnx-streaming-zipformer-fr-2023-04-14]|French| See [also](https://k2-fsa.github.io/sherpa/onnx/pretrained_models/online-transducer/zipformer-transducer-models.html#shaojieli-sherpa-onnx-streaming-zipformer-fr-2023-04-14-french)|
-
-
-
-
-#### Some pre-trained ASR models (Non-Streaming)
-
-
-
-Please see
-
- -
- -
- -
- -
- -
-
-for more models. The following table lists only **SOME** of them.
-
-|Name | Supported Languages| Description|
-|-----|-----|----|
-|[sherpa-onnx-nemo-parakeet-tdt-0.6b-v2-int8](https://k2-fsa.github.io/sherpa/onnx/pretrained_models/offline-transducer/nemo-transducer-models.html#sherpa-onnx-nemo-parakeet-tdt-0-6b-v2-int8-english)| English | It is converted from |
-|[Whisper tiny.en](https://github.com/k2-fsa/sherpa-onnx/releases/download/asr-models/sherpa-onnx-whisper-tiny.en.tar.bz2)|English| See [also](https://k2-fsa.github.io/sherpa/onnx/pretrained_models/whisper/tiny.en.html)|
-|[Moonshine tiny][Moonshine tiny]|English|See [also](https://github.com/usefulsensors/moonshine)|
-|[sherpa-onnx-zipformer-ctc-zh-int8-2025-07-03](https://k2-fsa.github.io/sherpa/onnx/pretrained_models/offline-ctc/icefall/zipformer.html#sherpa-onnx-zipformer-ctc-zh-int8-2025-07-03-chinese)|Chinese| A Zipformer CTC model|
-|[sherpa-onnx-sense-voice-zh-en-ja-ko-yue-2024-07-17][sherpa-onnx-sense-voice-zh-en-ja-ko-yue-2024-07-17]|Chinese, Cantonese, English, Korean, Japanese| 支持多种中文方言. See [also](https://k2-fsa.github.io/sherpa/onnx/sense-voice/index.html)|
-|[sherpa-onnx-paraformer-zh-2024-03-09][sherpa-onnx-paraformer-zh-2024-03-09]|Chinese, English| 也支持多种中文方言. See [also](https://k2-fsa.github.io/sherpa/onnx/pretrained_models/offline-paraformer/paraformer-models.html#csukuangfj-sherpa-onnx-paraformer-zh-2024-03-09-chinese-english)|
-|[sherpa-onnx-zipformer-ja-reazonspeech-2024-08-01][sherpa-onnx-zipformer-ja-reazonspeech-2024-08-01]|Japanese|See [also](https://k2-fsa.github.io/sherpa/onnx/pretrained_models/offline-transducer/zipformer-transducer-models.html#sherpa-onnx-zipformer-ja-reazonspeech-2024-08-01-japanese)|
-|[sherpa-onnx-nemo-transducer-giga-am-russian-2024-10-24][sherpa-onnx-nemo-transducer-giga-am-russian-2024-10-24]|Russian|See [also](https://k2-fsa.github.io/sherpa/onnx/pretrained_models/offline-transducer/nemo-transducer-models.html#sherpa-onnx-nemo-transducer-giga-am-russian-2024-10-24-russian)|
-|[sherpa-onnx-nemo-ctc-giga-am-russian-2024-10-24][sherpa-onnx-nemo-ctc-giga-am-russian-2024-10-24]|Russian| See [also](https://k2-fsa.github.io/sherpa/onnx/pretrained_models/offline-ctc/nemo/russian.html#sherpa-onnx-nemo-ctc-giga-am-russian-2024-10-24)|
-|[sherpa-onnx-zipformer-ru-2024-09-18][sherpa-onnx-zipformer-ru-2024-09-18]|Russian|See [also](https://k2-fsa.github.io/sherpa/onnx/pretrained_models/offline-transducer/zipformer-transducer-models.html#sherpa-onnx-zipformer-ru-2024-09-18-russian)|
-|[sherpa-onnx-zipformer-korean-2024-06-24][sherpa-onnx-zipformer-korean-2024-06-24]|Korean|See [also](https://k2-fsa.github.io/sherpa/onnx/pretrained_models/offline-transducer/zipformer-transducer-models.html#sherpa-onnx-zipformer-korean-2024-06-24-korean)|
-|[sherpa-onnx-zipformer-thai-2024-06-20][sherpa-onnx-zipformer-thai-2024-06-20]|Thai| See [also](https://k2-fsa.github.io/sherpa/onnx/pretrained_models/offline-transducer/zipformer-transducer-models.html#sherpa-onnx-zipformer-thai-2024-06-20-thai)|
-|[sherpa-onnx-telespeech-ctc-int8-zh-2024-06-04][sherpa-onnx-telespeech-ctc-int8-zh-2024-06-04]|Chinese| 支持多种方言. See [also](https://k2-fsa.github.io/sherpa/onnx/pretrained_models/telespeech/models.html#sherpa-onnx-telespeech-ctc-int8-zh-2024-06-04)|
-
-
-
-### Useful links
-
-- Documentation: https://k2-fsa.github.io/sherpa/onnx/
-- Bilibili 演示视频: https://search.bilibili.com/all?keyword=%E6%96%B0%E4%B8%80%E4%BB%A3Kaldi
-
-### How to reach us
-
-Please see
-https://k2-fsa.github.io/sherpa/social-groups.html
-for 新一代 Kaldi **微信交流群** and **QQ 交流群**.
-
-## Projects using sherpa-onnx
-
-### [Sherpa Voice / @siteed/sherpa-onnx.rn](https://github.com/deeeed/audiolab)
-
-> React Native wrapper and demo app for validating sherpa-onnx on iOS,
-> Android, and Web, including ASR, TTS, VAD, KWS, speaker ID, diarization,
-> language ID, punctuation, audio tagging, and speech enhancement.
-
-- [NPM package](https://www.npmjs.com/package/@siteed/sherpa-onnx.rn)
-- [Live demo](https://deeeed.github.io/audiolab/sherpa-voice/)
-
-### [Speed of Sound](https://github.com/zugaldia/speedofsound)
-
-> A voice-typing application for the Linux desktop (GTK4/Adwaita).
-> It captures microphone audio, transcribes it offline using Sherpa ONNX ASR models,
-> optionally polishes the text with an LLM, and types the result into the active window
-> via XDG Remote Desktop Portal keyboard simulation.
-
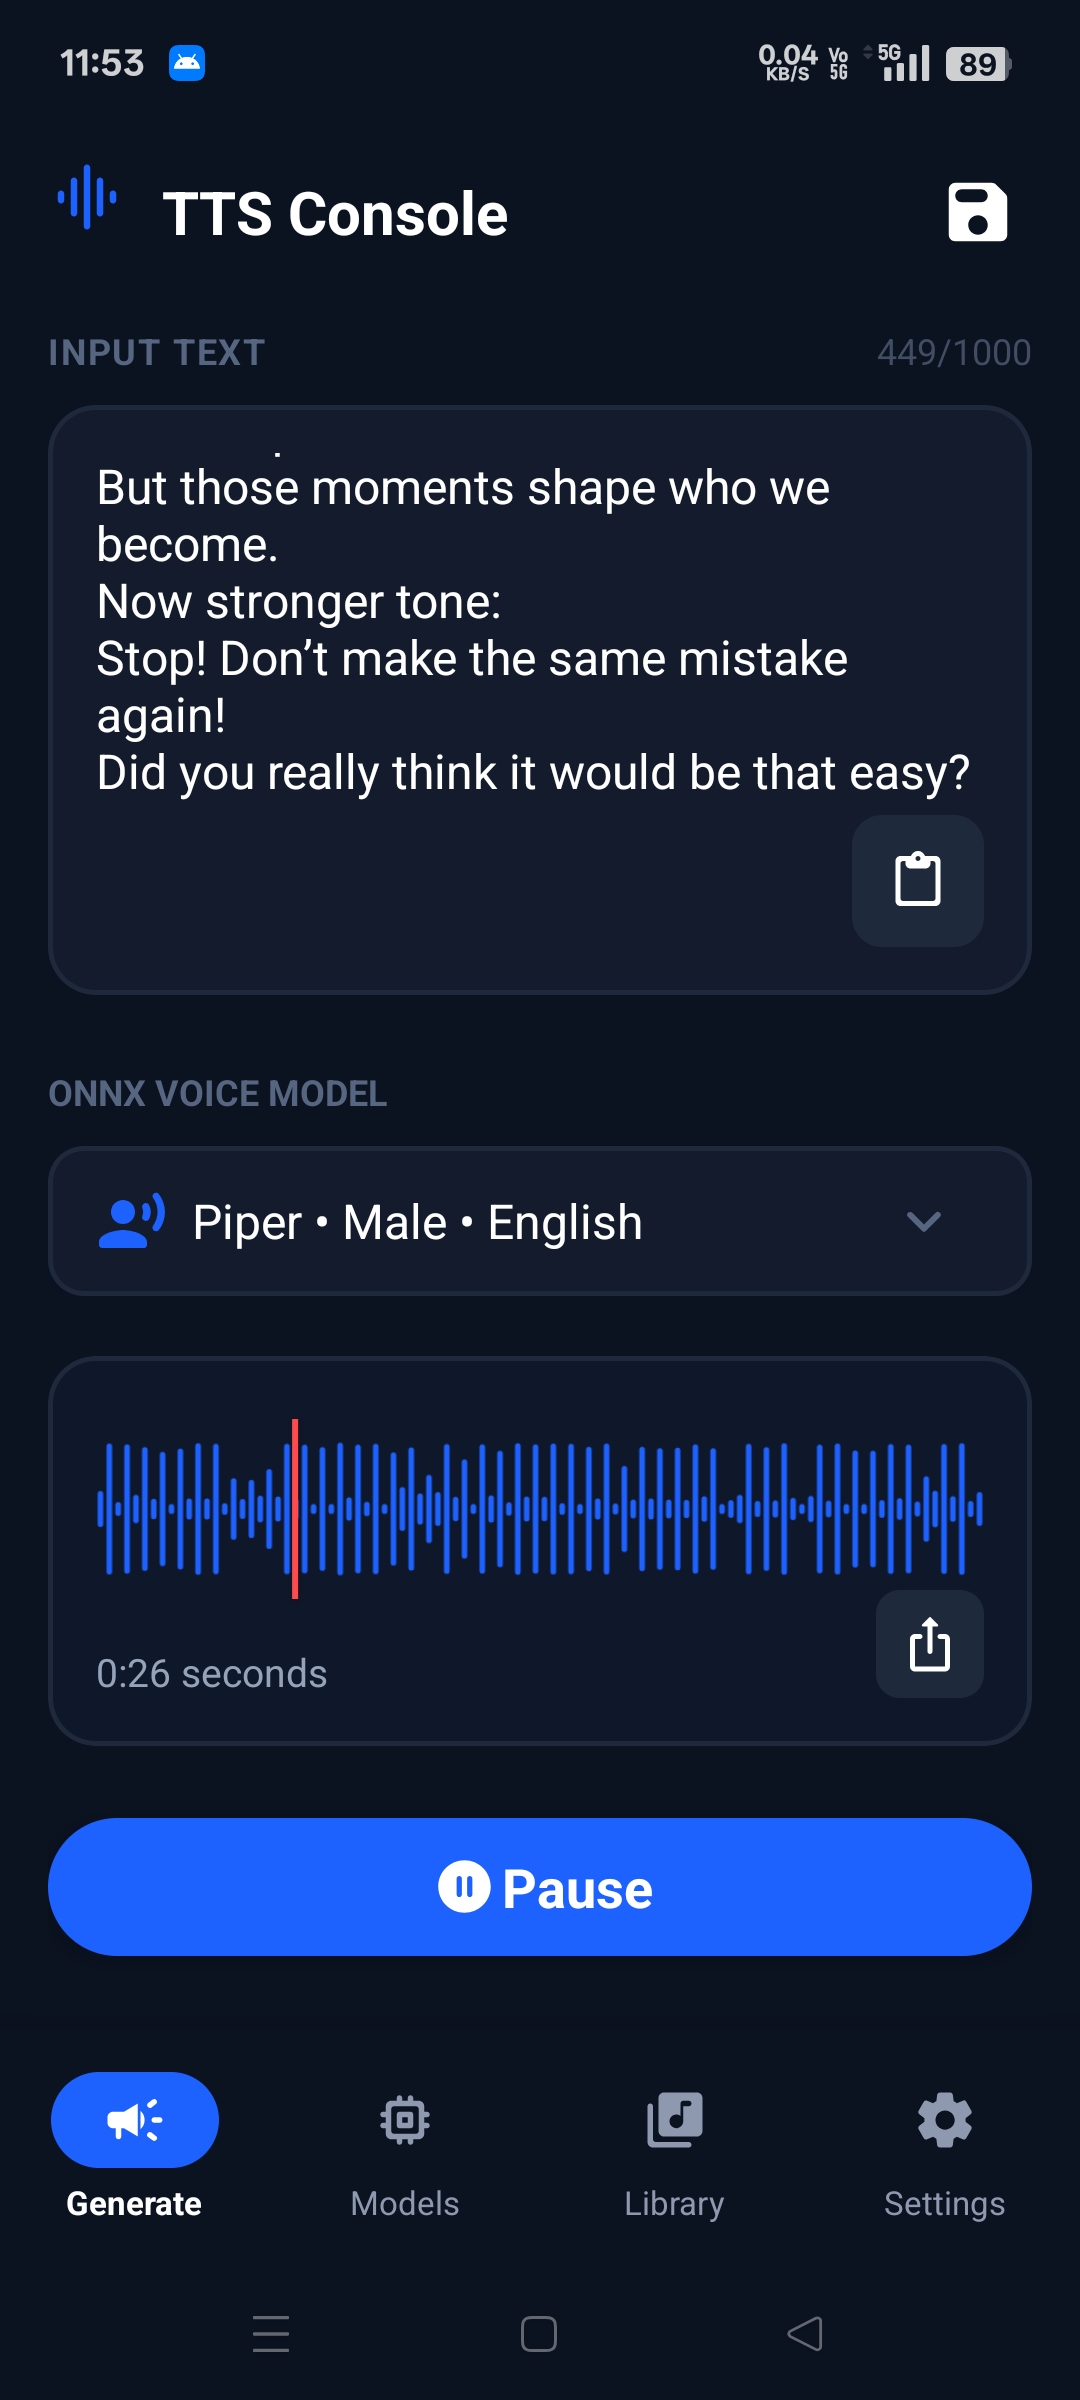
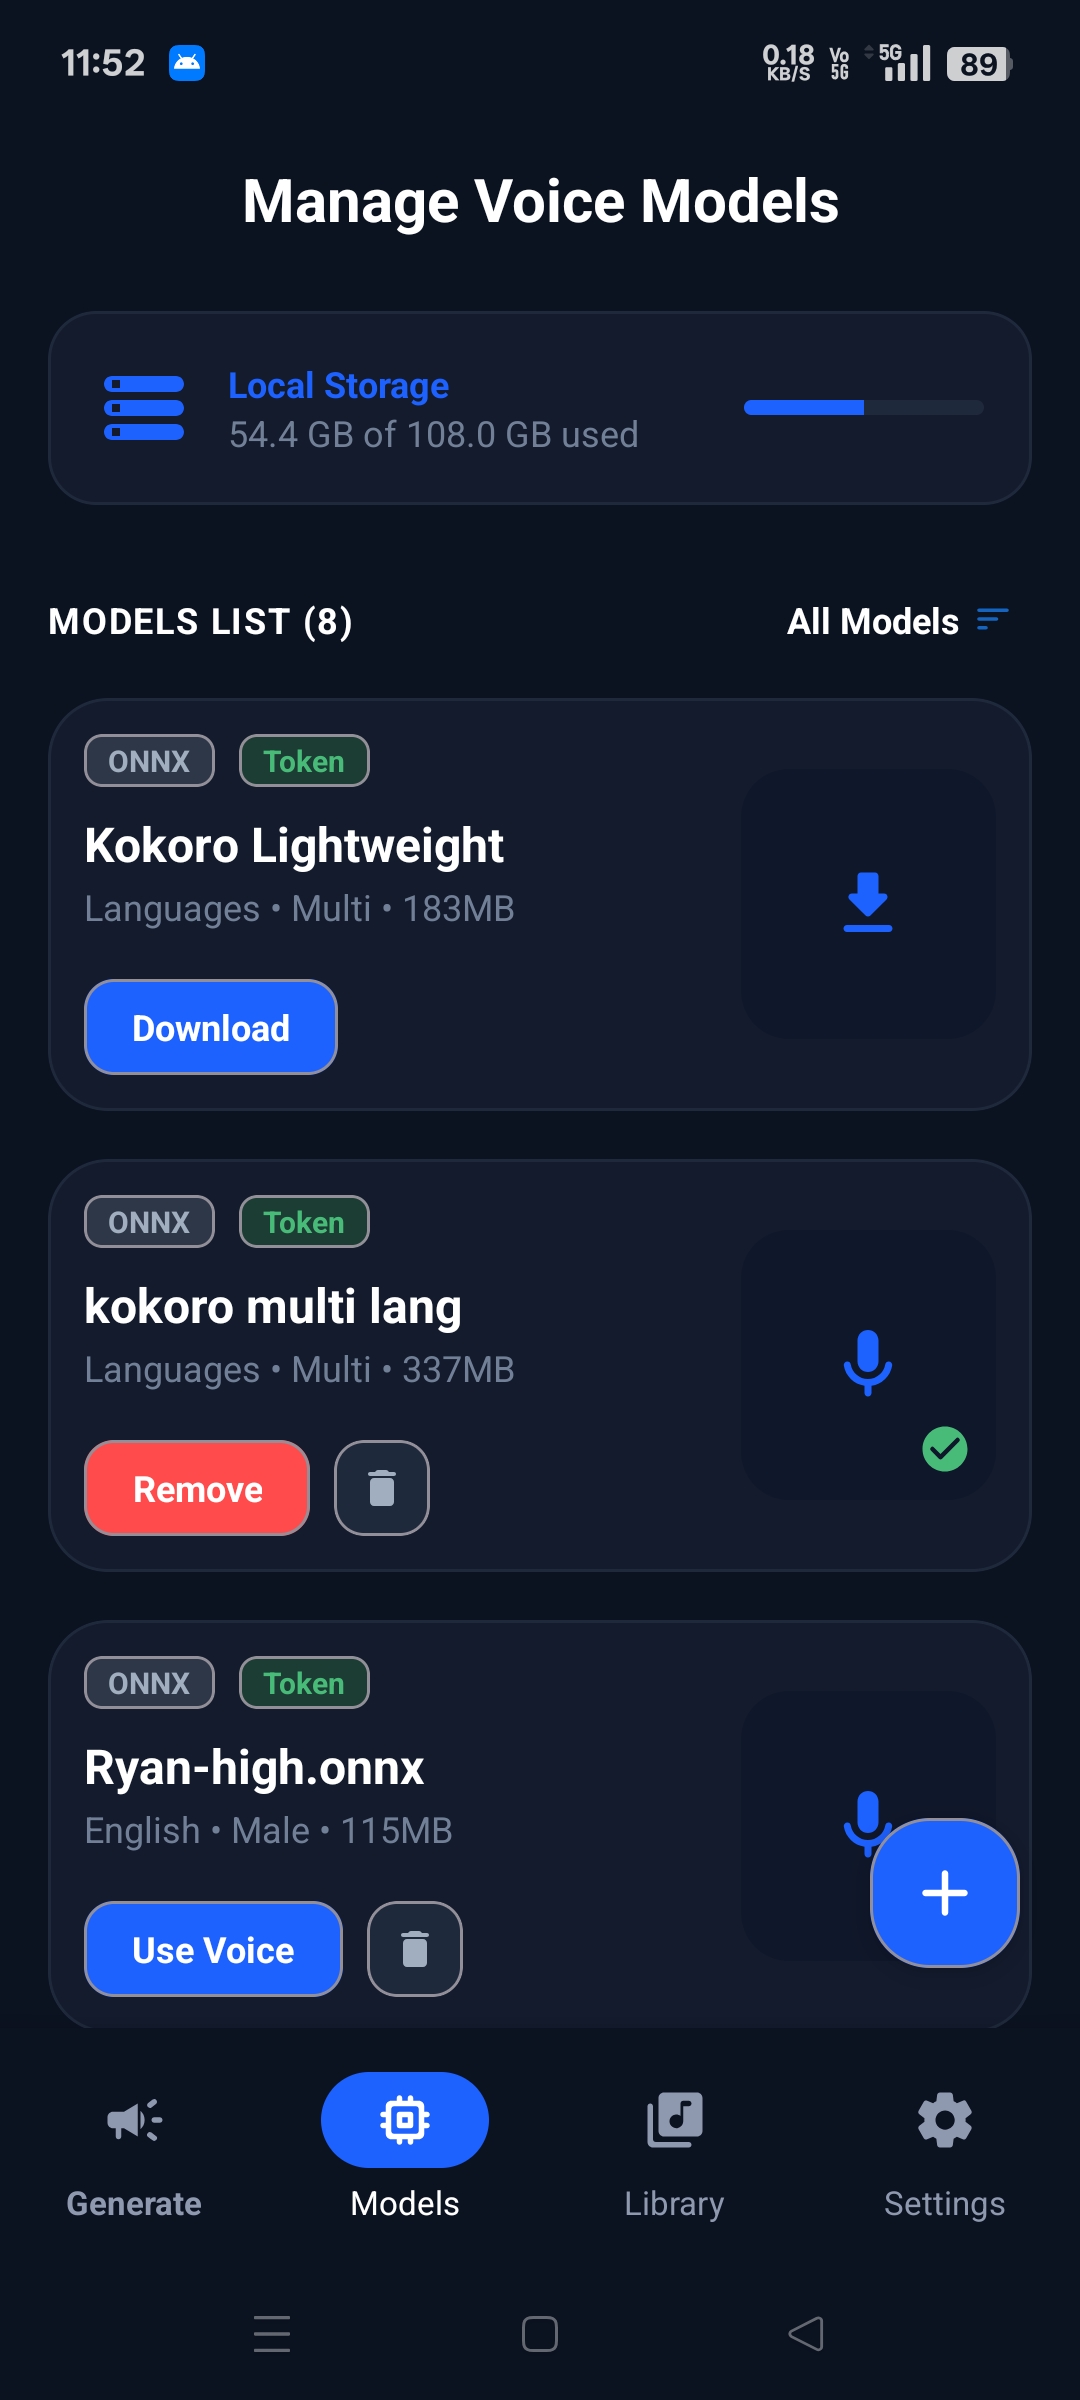
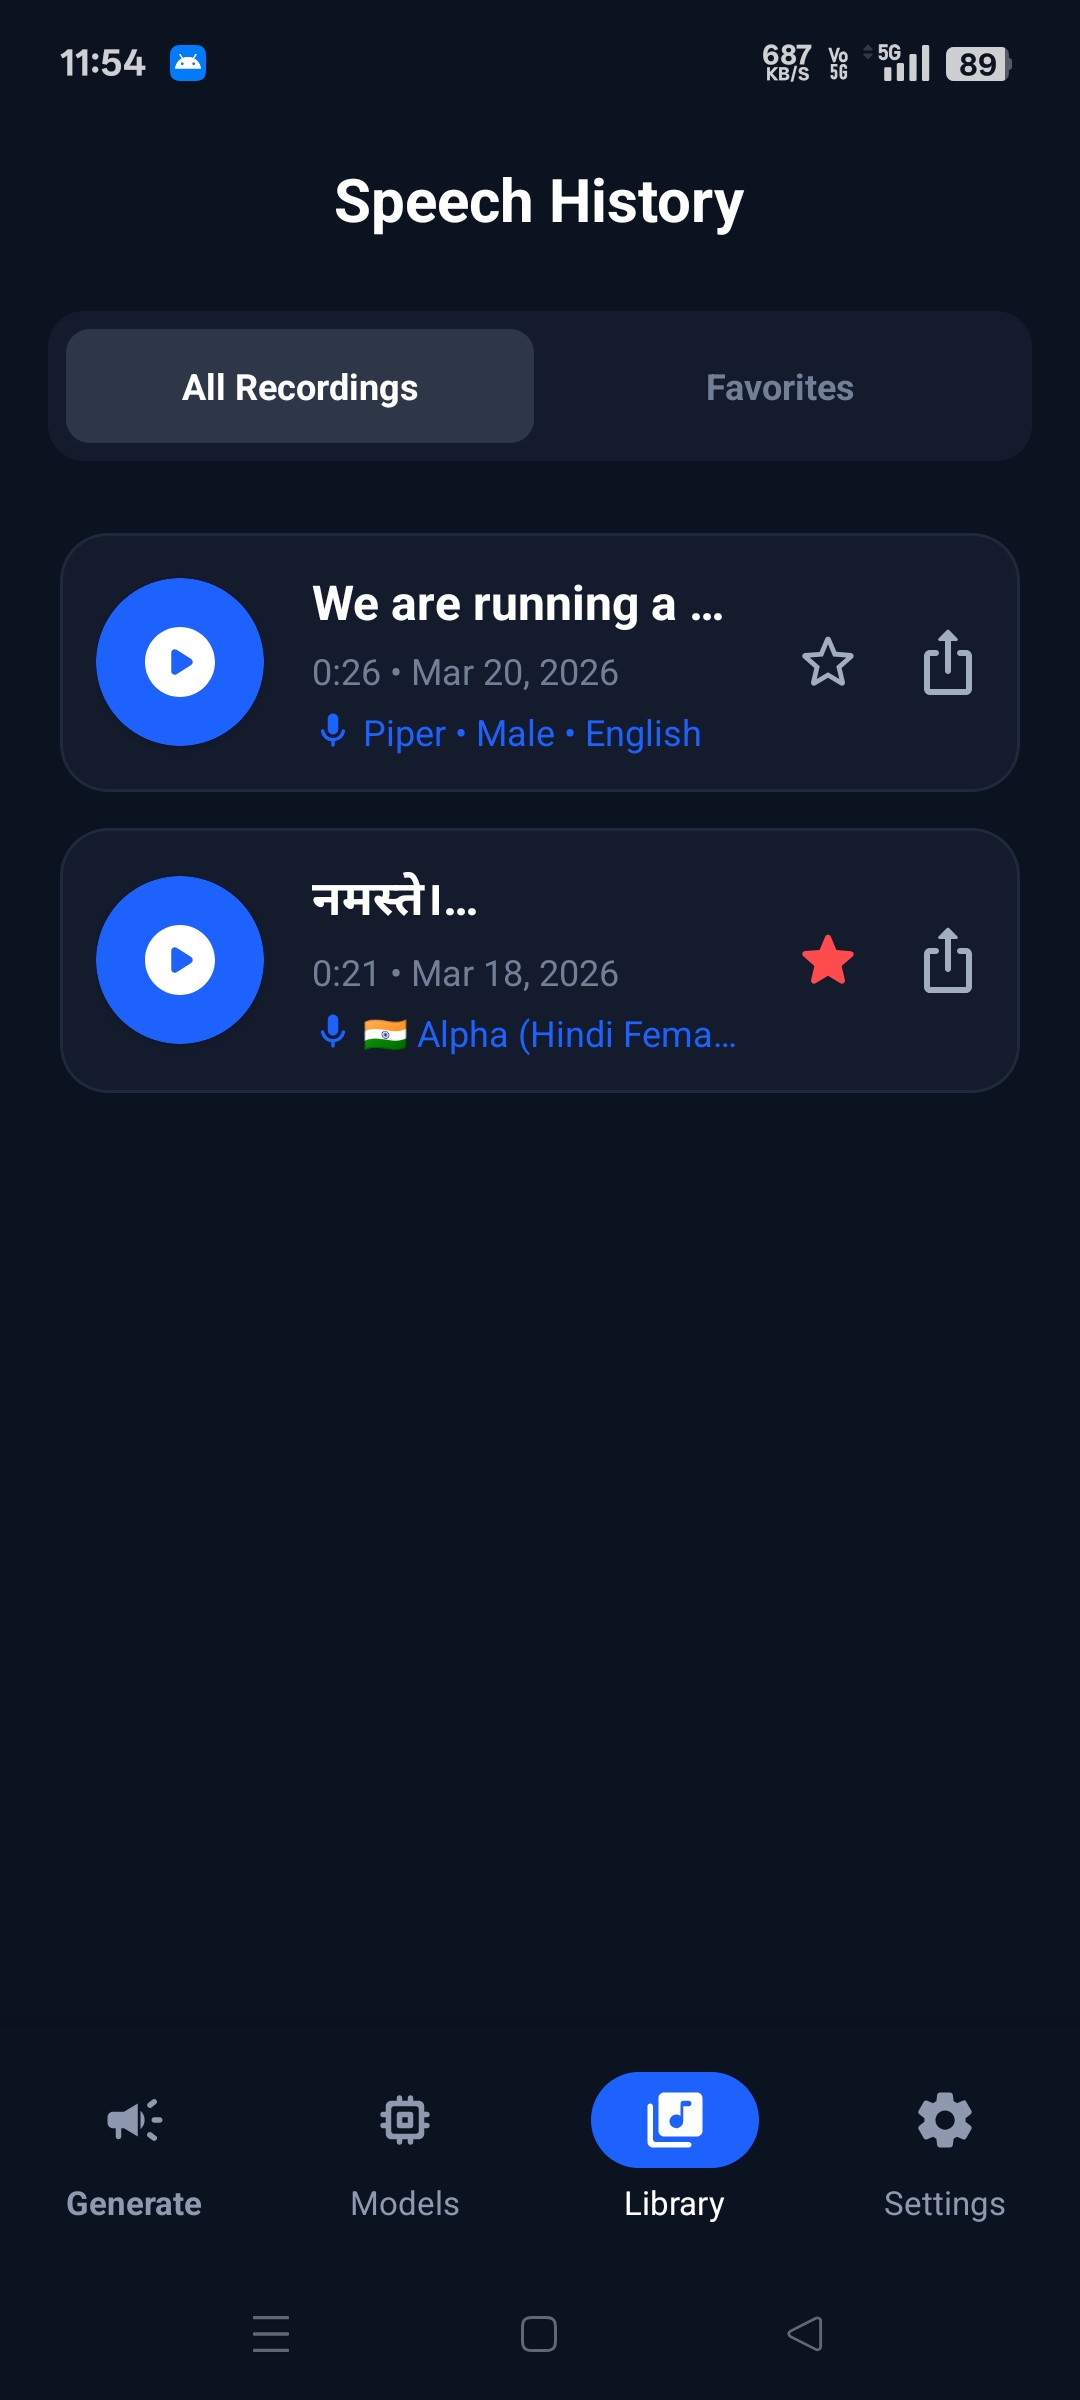
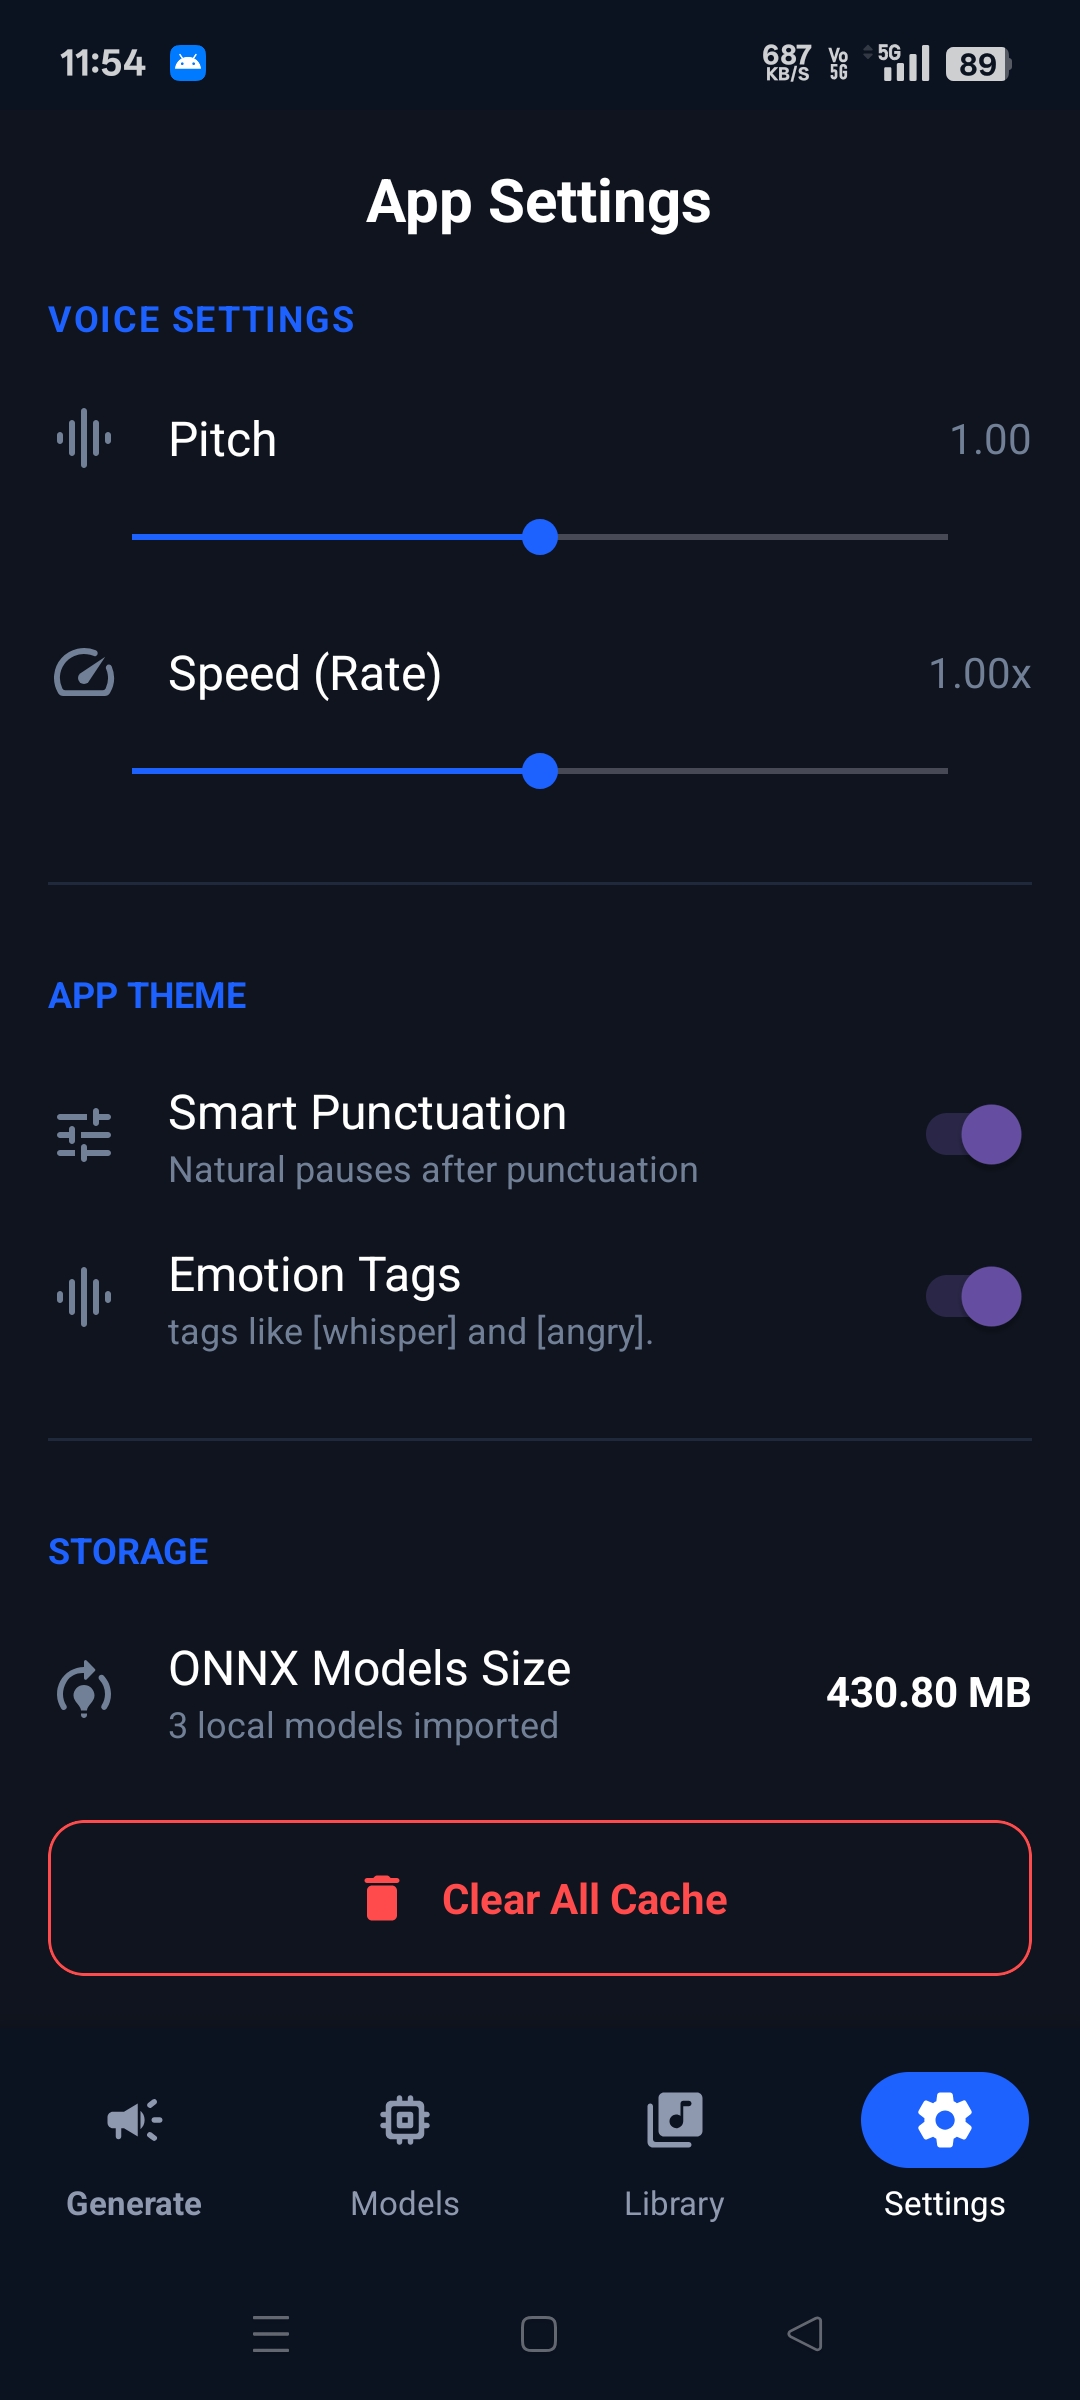
-### [VoxSherpa TTS](https://github.com/CodeBySonu95/VoxSherpa-TTS)
-
-> VoxSherpa TTS is a 100% offline Android Text-to-Speech app powered by Sherpa-ONNX.
-> It supports Kokoro-82M, Piper, and VITS engines with multilingual support including
-> Hindi, English, British English, Japanese, Chinese and 50+ more languages.
-
-- [Download APK (All Versions)](https://github.com/CodeBySonu95/VoxSherpa-TTS/releases)
-- Android 11+ · 100% offline · No telemetry
-
-
-
-| Generate | Models | Library | Settings |
-|:---:|:---:|:---:|:---:|
-|
|
|
|
|
-
-
- Streaming ASR and TTS based on FastAPI
-
-
-It shows how to use the ASR and TTS Python APIs with FastAPI.
-
-
-### [腾讯会议摸鱼工具 TMSpeech](https://github.com/jxlpzqc/TMSpeech)
-
-Uses streaming ASR in C# with graphical user interface.
-
-Video demo in Chinese: [【开源】Windows实时字幕软件(网课/开会必备)](https://www.bilibili.com/video/BV1rX4y1p7Nx)
-
-### [lol互动助手](https://github.com/l1veIn/lol-wom-electron)
-
-It uses the JavaScript API of sherpa-onnx along with [Electron](https://electronjs.org/)
-
-Video demo in Chinese: [爆了!炫神教你开打字挂!真正影响胜率的英雄联盟工具!英雄联盟的最后一块拼图!和游戏中的每个人无障碍沟通!](https://www.bilibili.com/video/BV142tje9E74)
-
-### [Sherpa-ONNX 语音识别服务器](https://github.com/hfyydd/sherpa-onnx-server)
-
-A server based on nodejs providing Restful API for speech recognition.
-
-### [QSmartAssistant](https://github.com/xinhecuican/QSmartAssistant)
-
-一个模块化,全过程可离线,低占用率的对话机器人/智能音箱
-
-It uses QT. Both [ASR](https://github.com/xinhecuican/QSmartAssistant/blob/master/doc/%E5%AE%89%E8%A3%85.md#asr)
-and [TTS](https://github.com/xinhecuican/QSmartAssistant/blob/master/doc/%E5%AE%89%E8%A3%85.md#tts)
-are used.
-
-### [Flutter-EasySpeechRecognition](https://github.com/Jason-chen-coder/Flutter-EasySpeechRecognition)
-
-It extends [./flutter-examples/streaming_asr](./flutter-examples/streaming_asr) by
-downloading models inside the app to reduce the size of the app.
-
-Note: [[Team B] Sherpa AI backend](https://github.com/umgc/spring2025/pull/82) also uses
-sherpa-onnx in a Flutter APP.
-
-### [sherpa-onnx-unity](https://github.com/xue-fei/sherpa-onnx-unity)
-
-sherpa-onnx in Unity. See also [#1695](https://github.com/k2-fsa/sherpa-onnx/issues/1695),
-[#1892](https://github.com/k2-fsa/sherpa-onnx/issues/1892), and [#1859](https://github.com/k2-fsa/sherpa-onnx/issues/1859)
-
-### [xiaozhi-esp32-server](https://github.com/xinnan-tech/xiaozhi-esp32-server)
-
-本项目为xiaozhi-esp32提供后端服务,帮助您快速搭建ESP32设备控制服务器
-Backend service for xiaozhi-esp32, helps you quickly build an ESP32 device control server.
-
-See also
-
- - [ASR新增轻量级sherpa-onnx-asr](https://github.com/xinnan-tech/xiaozhi-esp32-server/issues/315)
- - [feat: ASR增加sherpa-onnx模型](https://github.com/xinnan-tech/xiaozhi-esp32-server/pull/379)
-
-### [KaithemAutomation](https://github.com/EternityForest/KaithemAutomation)
-
-Pure Python, GUI-focused home automation/consumer grade SCADA.
-
-It uses TTS from sherpa-onnx. See also [✨ Speak command that uses the new globally configured TTS model.](https://github.com/EternityForest/KaithemAutomation/commit/8e64d2b138725e426532f7d66bb69dd0b4f53693)
-
-### [Open-XiaoAI KWS](https://github.com/idootop/open-xiaoai-kws)
-
-Enable custom wake word for XiaoAi Speakers. 让小爱音箱支持自定义唤醒词。
-
-Video demo in Chinese: [小爱同学启动~˶╹ꇴ╹˶!](https://www.bilibili.com/video/BV1YfVUz5EMj)
-
-### [C++ WebSocket ASR Server](https://github.com/mawwalker/stt-server)
-
-It provides a WebSocket server based on C++ for ASR using sherpa-onnx.
-
-### [Go WebSocket Server](https://github.com/bbeyondllove/asr_server)
-
-It provides a WebSocket server based on the Go programming language for sherpa-onnx.
-
-### [Making robot Paimon, Ep10 "The AI Part 1"](https://www.youtube.com/watch?v=KxPKkwxGWZs)
-
-It is a [YouTube video](https://www.youtube.com/watch?v=KxPKkwxGWZs),
-showing how the author tried to use AI so he can have a conversation with Paimon.
-
-It uses sherpa-onnx for speech-to-text and text-to-speech.
-|1|
-|---|
-||
-
-### [TtsReader - Desktop application](https://github.com/ys-pro-duction/TtsReader)
-
-A desktop text-to-speech application built using Kotlin Multiplatform.
-
-### [MentraOS](https://github.com/Mentra-Community/MentraOS)
-
-> Smart glasses OS, with dozens of built-in apps. Users get AI assistant, notifications,
-> translation, screen mirror, captions, and more. Devs get to write 1 app that runs on
-> any pair of smart glasses.
-
-It uses sherpa-onnx for real-time speech recognition on iOS and Android devices.
-See also
-
-It uses Swift for iOS and Java for Android.
-
-### [flet_sherpa_onnx](https://github.com/SamYuan1990/flet_sherpa_onnx)
-
-Flet ASR/STT component based on sherpa-onnx.
-Example [a chat box agent](https://github.com/SamYuan1990/i18n-agent-action)
-
-### [achatbot-go](https://github.com/ai-bot-pro/achatbot-go)
-
-a multimodal chatbot based on go with sherpa-onnx's speech lib api.
-
-### [fcitx5-vinput](https://github.com/xifan2333/fcitx5-vinput)
-
-Local offline voice input plugin for [Fcitx5](https://github.com/fcitx/fcitx5) (Linux input method framework).
-It uses C++ with offline ASR for speech recognition, supporting push-to-talk,
-command mode, and optional LLM post-processing.
-
-Video demo in Chinese: [fcitx5-vinput](https://www.bilibili.com/video/BV1a6cUzVE6F)
-
-### [Wake Word](https://github.com/analyticsinmotion/wake-word)
-
-A VS Code extension for hands-free voice-activated coding. It uses sherpa-onnx for real-time
-keyword spotting (KWS) to detect custom wake phrases and trigger VS Code commands by voice.
-Audio capture is handled by [decibri](https://github.com/analyticsinmotion/decibri), a
-cross-platform Node.js microphone streaming library with prebuilt native binaries.
-
-- [VS Code Marketplace](https://marketplace.visualstudio.com/items?itemName=analytics-in-motion.wake-word)
-- [Open VSX](https://open-vsx.org/extension/analytics-in-motion/wake-word)
-- [decibri integration guides for sherpa-onnx](https://decibri.dev/docs/node/integrations/sherpa-onnx-stt.html)
-
-### [SmartSub](https://github.com/buxuku/SmartSub)
-
-> SmartSub is a local-first cross-platform desktop application for the complete subtitle production pipeline: audio/video transcription, subtitle translation, proofreading, and subtitle burning/muxing.
->
-> It natively integrates sherpa-onnx to power three offline ASR engines — FunASR, Qwen3-ASR, and FireRedASR — delivering high-accuracy Chinese and multilingual speech recognition entirely on-device, with no file uploads required.
-
-[silero-vad]: https://github.com/snakers4/silero-vad
-[Raspberry Pi]: https://www.raspberrypi.com/
-[RV1126]: https://www.rock-chips.com/uploads/pdf/2022.8.26/191/RV1126%20Brief%20Datasheet.pdf
-[LicheePi4A]: https://sipeed.com/licheepi4a
-[VisionFive 2]: https://www.starfivetech.com/en/site/boards
-[旭日X3派]: https://developer.horizon.ai/api/v1/fileData/documents_pi/index.html
-[爱芯派]: https://wiki.sipeed.com/hardware/zh/maixIII/ax-pi/axpi.html
-[hf-space-speaker-diarization]: https://huggingface.co/spaces/k2-fsa/speaker-diarization
-[hf-space-speaker-diarization-cn]: https://hf.qhduan.com/spaces/k2-fsa/speaker-diarization
-[hf-space-asr]: https://huggingface.co/spaces/k2-fsa/automatic-speech-recognition
-[hf-space-asr-cn]: https://hf.qhduan.com/spaces/k2-fsa/automatic-speech-recognition
-[Whisper]: https://github.com/openai/whisper
-[hf-space-asr-whisper]: https://huggingface.co/spaces/k2-fsa/automatic-speech-recognition-with-whisper
-[hf-space-asr-whisper-cn]: https://hf.qhduan.com/spaces/k2-fsa/automatic-speech-recognition-with-whisper
-[hf-space-tts]: https://huggingface.co/spaces/k2-fsa/text-to-speech
-[hf-space-tts-cn]: https://hf.qhduan.com/spaces/k2-fsa/text-to-speech
-[hf-space-subtitle]: https://huggingface.co/spaces/k2-fsa/generate-subtitles-for-videos
-[hf-space-subtitle-cn]: https://hf.qhduan.com/spaces/k2-fsa/generate-subtitles-for-videos
-[hf-space-audio-tagging]: https://huggingface.co/spaces/k2-fsa/audio-tagging
-[hf-space-audio-tagging-cn]: https://hf.qhduan.com/spaces/k2-fsa/audio-tagging
-[hf-space-source-separation]: https://huggingface.co/spaces/k2-fsa/source-separation
-[hf-space-source-separation-cn]: https://hf.qhduan.com/spaces/k2-fsa/source-separation
-[hf-space-slid-whisper]: https://huggingface.co/spaces/k2-fsa/spoken-language-identification
-[hf-space-slid-whisper-cn]: https://hf.qhduan.com/spaces/k2-fsa/spoken-language-identification
-[wasm-hf-vad]: https://huggingface.co/spaces/k2-fsa/web-assembly-vad-sherpa-onnx
-[wasm-ms-vad]: https://modelscope.cn/studios/csukuangfj/web-assembly-vad-sherpa-onnx
-[wasm-hf-streaming-asr-zh-en-zipformer]: https://huggingface.co/spaces/k2-fsa/web-assembly-asr-sherpa-onnx-zh-en
-[wasm-ms-streaming-asr-zh-en-zipformer]: https://modelscope.cn/studios/k2-fsa/web-assembly-asr-sherpa-onnx-zh-en
-[wasm-hf-streaming-asr-zh-en-paraformer]: https://huggingface.co/spaces/k2-fsa/web-assembly-asr-sherpa-onnx-zh-en-paraformer
-[wasm-ms-streaming-asr-zh-en-paraformer]: https://modelscope.cn/studios/k2-fsa/web-assembly-asr-sherpa-onnx-zh-en-paraformer
-[Paraformer-large]: https://www.modelscope.cn/models/damo/speech_paraformer-large_asr_nat-zh-cn-16k-common-vocab8404-pytorch/summary
-[wasm-hf-streaming-asr-zh-en-yue-paraformer]: https://huggingface.co/spaces/k2-fsa/web-assembly-asr-sherpa-onnx-zh-cantonese-en-paraformer
-[wasm-ms-streaming-asr-zh-en-yue-paraformer]: https://modelscope.cn/studios/k2-fsa/web-assembly-asr-sherpa-onnx-zh-cantonese-en-paraformer
-[wasm-hf-streaming-asr-en-zipformer]: https://huggingface.co/spaces/k2-fsa/web-assembly-asr-sherpa-onnx-en
-[wasm-ms-streaming-asr-en-zipformer]: https://modelscope.cn/studios/k2-fsa/web-assembly-asr-sherpa-onnx-en
-[SenseVoice]: https://github.com/FunAudioLLM/SenseVoice
-[wasm-hf-vad-asr-zh-zipformer-ctc-07-03]: https://huggingface.co/spaces/k2-fsa/web-assembly-vad-asr-sherpa-onnx-zh-zipformer-ctc
-[wasm-ms-vad-asr-zh-zipformer-ctc-07-03]: https://modelscope.cn/studios/csukuangfj/web-assembly-vad-asr-sherpa-onnx-zh-zipformer-ctc/summary
-[wasm-hf-vad-asr-zh-en-ko-ja-yue-sense-voice]: https://huggingface.co/spaces/k2-fsa/web-assembly-vad-asr-sherpa-onnx-zh-en-ja-ko-cantonese-sense-voice
-[wasm-ms-vad-asr-zh-en-ko-ja-yue-sense-voice]: https://www.modelscope.cn/studios/csukuangfj/web-assembly-vad-asr-sherpa-onnx-zh-en-jp-ko-cantonese-sense-voice
-[wasm-hf-vad-asr-en-whisper-tiny-en]: https://huggingface.co/spaces/k2-fsa/web-assembly-vad-asr-sherpa-onnx-en-whisper-tiny
-[wasm-ms-vad-asr-en-whisper-tiny-en]: https://www.modelscope.cn/studios/csukuangfj/web-assembly-vad-asr-sherpa-onnx-en-whisper-tiny
-[wasm-hf-vad-asr-en-moonshine-tiny-en]: https://huggingface.co/spaces/k2-fsa/web-assembly-vad-asr-sherpa-onnx-en-moonshine-tiny
-[wasm-ms-vad-asr-en-moonshine-tiny-en]: https://www.modelscope.cn/studios/csukuangfj/web-assembly-vad-asr-sherpa-onnx-en-moonshine-tiny
-[wasm-hf-vad-asr-en-zipformer-gigaspeech]: https://huggingface.co/spaces/k2-fsa/web-assembly-vad-asr-sherpa-onnx-en-zipformer-gigaspeech
-[wasm-ms-vad-asr-en-zipformer-gigaspeech]: https://www.modelscope.cn/studios/k2-fsa/web-assembly-vad-asr-sherpa-onnx-en-zipformer-gigaspeech
-[wasm-hf-vad-asr-zh-zipformer-wenetspeech]: https://huggingface.co/spaces/k2-fsa/web-assembly-vad-asr-sherpa-onnx-zh-zipformer-wenetspeech
-[wasm-ms-vad-asr-zh-zipformer-wenetspeech]: https://www.modelscope.cn/studios/k2-fsa/web-assembly-vad-asr-sherpa-onnx-zh-zipformer-wenetspeech
-[reazonspeech]: https://research.reazon.jp/_static/reazonspeech_nlp2023.pdf
-[wasm-hf-vad-asr-ja-zipformer-reazonspeech]: https://huggingface.co/spaces/k2-fsa/web-assembly-vad-asr-sherpa-onnx-ja-zipformer
-[wasm-ms-vad-asr-ja-zipformer-reazonspeech]: https://www.modelscope.cn/studios/csukuangfj/web-assembly-vad-asr-sherpa-onnx-ja-zipformer
-[gigaspeech2]: https://github.com/speechcolab/gigaspeech2
-[wasm-hf-vad-asr-th-zipformer-gigaspeech2]: https://huggingface.co/spaces/k2-fsa/web-assembly-vad-asr-sherpa-onnx-th-zipformer
-[wasm-ms-vad-asr-th-zipformer-gigaspeech2]: https://www.modelscope.cn/studios/csukuangfj/web-assembly-vad-asr-sherpa-onnx-th-zipformer
-[telespeech-asr]: https://github.com/tele-ai/telespeech-asr
-[wasm-hf-vad-asr-zh-telespeech]: https://huggingface.co/spaces/k2-fsa/web-assembly-vad-asr-sherpa-onnx-zh-telespeech
-[wasm-ms-vad-asr-zh-telespeech]: https://www.modelscope.cn/studios/k2-fsa/web-assembly-vad-asr-sherpa-onnx-zh-telespeech
-[wasm-hf-vad-asr-zh-en-paraformer-large]: https://huggingface.co/spaces/k2-fsa/web-assembly-vad-asr-sherpa-onnx-zh-en-paraformer
-[wasm-ms-vad-asr-zh-en-paraformer-large]: https://www.modelscope.cn/studios/k2-fsa/web-assembly-vad-asr-sherpa-onnx-zh-en-paraformer
-[wasm-hf-vad-asr-zh-en-paraformer-small]: https://huggingface.co/spaces/k2-fsa/web-assembly-vad-asr-sherpa-onnx-zh-en-paraformer-small
-[wasm-ms-vad-asr-zh-en-paraformer-small]: https://www.modelscope.cn/studios/k2-fsa/web-assembly-vad-asr-sherpa-onnx-zh-en-paraformer-small
-[dolphin]: https://github.com/dataoceanai/dolphin
-[wasm-ms-vad-asr-multi-lang-dolphin-base]: https://modelscope.cn/studios/csukuangfj/web-assembly-vad-asr-sherpa-onnx-multi-lang-dophin-ctc
-[wasm-hf-vad-asr-multi-lang-dolphin-base]: https://huggingface.co/spaces/k2-fsa/web-assembly-vad-asr-sherpa-onnx-multi-lang-dophin-ctc
-
-[wasm-hf-tts-matcha-zh-en]: https://huggingface.co/spaces/k2-fsa/web-assembly-zh-en-tts-matcha
-[wasm-hf-tts-matcha-zh]: https://huggingface.co/spaces/k2-fsa/web-assembly-zh-tts-matcha
-[wasm-ms-tts-matcha-zh-en]: https://modelscope.cn/studios/csukuangfj/web-assembly-zh-en-tts-matcha
-[wasm-ms-tts-matcha-zh]: https://modelscope.cn/studios/csukuangfj/web-assembly-zh-tts-matcha
-[wasm-hf-tts-matcha-en]: https://huggingface.co/spaces/k2-fsa/web-assembly-en-tts-matcha
-[wasm-ms-tts-matcha-en]: https://modelscope.cn/studios/csukuangfj/web-assembly-en-tts-matcha
-[wasm-hf-tts-piper-en]: https://huggingface.co/spaces/k2-fsa/web-assembly-tts-sherpa-onnx-en
-[wasm-ms-tts-piper-en]: https://modelscope.cn/studios/k2-fsa/web-assembly-tts-sherpa-onnx-en
-[wasm-hf-tts-piper-de]: https://huggingface.co/spaces/k2-fsa/web-assembly-tts-sherpa-onnx-de
-[wasm-ms-tts-piper-de]: https://modelscope.cn/studios/k2-fsa/web-assembly-tts-sherpa-onnx-de
-[wasm-hf-speaker-diarization]: https://huggingface.co/spaces/k2-fsa/web-assembly-speaker-diarization-sherpa-onnx
-[wasm-ms-speaker-diarization]: https://www.modelscope.cn/studios/csukuangfj/web-assembly-speaker-diarization-sherpa-onnx
-[wasm-hf-voice-cloning-zipvoice]: https://huggingface.co/spaces/k2-fsa/web-assembly-zh-en-tts-zipvoice
-[wasm-ms-voice-cloning-zipvoice]: https://modelscope.cn/studios/csukuangfj/web-assembly-zh-en-tts-zipvoice
-[wasm-hf-voice-cloning-pocket]: https://huggingface.co/spaces/k2-fsa/web-assembly-en-tts-pocket
-[wasm-ms-voice-cloning-pocket]: https://modelscope.cn/studios/csukuangfj/web-assembly-en-tts-pocket
-[apk-speaker-diarization]: https://k2-fsa.github.io/sherpa/onnx/speaker-diarization/apk.html
-[apk-speaker-diarization-cn]: https://k2-fsa.github.io/sherpa/onnx/speaker-diarization/apk-cn.html
-[apk-streaming-asr]: https://k2-fsa.github.io/sherpa/onnx/android/apk.html
-[apk-streaming-asr-cn]: https://k2-fsa.github.io/sherpa/onnx/android/apk-cn.html
-[apk-simula-streaming-asr]: https://k2-fsa.github.io/sherpa/onnx/android/apk-simulate-streaming-asr.html
-[apk-simula-streaming-asr-cn]: https://k2-fsa.github.io/sherpa/onnx/android/apk-simulate-streaming-asr-cn.html
-[apk-tts]: https://k2-fsa.github.io/sherpa/onnx/tts/apk-engine.html
-[apk-tts-cn]: https://k2-fsa.github.io/sherpa/onnx/tts/apk-engine-cn.html
-[apk-vad]: https://k2-fsa.github.io/sherpa/onnx/vad/apk.html
-[apk-vad-cn]: https://k2-fsa.github.io/sherpa/onnx/vad/apk-cn.html
-[apk-vad-asr]: https://k2-fsa.github.io/sherpa/onnx/vad/apk-asr.html
-[apk-vad-asr-cn]: https://k2-fsa.github.io/sherpa/onnx/vad/apk-asr-cn.html
-[apk-2pass]: https://k2-fsa.github.io/sherpa/onnx/android/apk-2pass.html
-[apk-2pass-cn]: https://k2-fsa.github.io/sherpa/onnx/android/apk-2pass-cn.html
-[apk-at]: https://k2-fsa.github.io/sherpa/onnx/audio-tagging/apk.html
-[apk-at-cn]: https://k2-fsa.github.io/sherpa/onnx/audio-tagging/apk-cn.html
-[apk-at-wearos]: https://k2-fsa.github.io/sherpa/onnx/audio-tagging/apk-wearos.html
-[apk-at-wearos-cn]: https://k2-fsa.github.io/sherpa/onnx/audio-tagging/apk-wearos-cn.html
-[apk-sid]: https://k2-fsa.github.io/sherpa/onnx/speaker-identification/apk.html
-[apk-sid-cn]: https://k2-fsa.github.io/sherpa/onnx/speaker-identification/apk-cn.html
-[apk-slid]: https://k2-fsa.github.io/sherpa/onnx/spoken-language-identification/apk.html
-[apk-slid-cn]: https://k2-fsa.github.io/sherpa/onnx/spoken-language-identification/apk-cn.html
-[apk-kws]: https://k2-fsa.github.io/sherpa/onnx/kws/apk.html
-[apk-kws-cn]: https://k2-fsa.github.io/sherpa/onnx/kws/apk-cn.html
-[apk-flutter-streaming-asr]: https://k2-fsa.github.io/sherpa/onnx/flutter/pre-built-app.html#streaming-speech-recognition-stt-asr
-[apk-flutter-streaming-asr-cn]: https://k2-fsa.github.io/sherpa/onnx/flutter/pre-built-app.html#streaming-speech-recognition-stt-asr
-[flutter-tts-android]: https://k2-fsa.github.io/sherpa/onnx/flutter/tts-android.html
-[flutter-tts-android-cn]: https://k2-fsa.github.io/sherpa/onnx/flutter/tts-android-cn.html
-[flutter-tts-linux]: https://k2-fsa.github.io/sherpa/onnx/flutter/tts-linux.html
-[flutter-tts-linux-cn]: https://k2-fsa.github.io/sherpa/onnx/flutter/tts-linux-cn.html
-[flutter-tts-macos-x64]: https://k2-fsa.github.io/sherpa/onnx/flutter/tts-macos-x64.html
-[flutter-tts-macos-arm64-cn]: https://k2-fsa.github.io/sherpa/onnx/flutter/tts-macos-arm64-cn.html
-[flutter-tts-macos-arm64]: https://k2-fsa.github.io/sherpa/onnx/flutter/tts-macos-arm64.html
-[flutter-tts-macos-x64-cn]: https://k2-fsa.github.io/sherpa/onnx/flutter/tts-macos-x64-cn.html
-[flutter-tts-win-x64]: https://k2-fsa.github.io/sherpa/onnx/flutter/tts-win.html
-[flutter-tts-win-x64-cn]: https://k2-fsa.github.io/sherpa/onnx/flutter/tts-win-cn.html
-[lazarus-subtitle]: https://k2-fsa.github.io/sherpa/onnx/lazarus/download-generated-subtitles.html
-[lazarus-subtitle-cn]: https://k2-fsa.github.io/sherpa/onnx/lazarus/download-generated-subtitles-cn.html
-[asr-models]: https://github.com/k2-fsa/sherpa-onnx/releases/tag/asr-models
-[tts-models]: https://github.com/k2-fsa/sherpa-onnx/releases/tag/tts-models
-[vad-models]: https://github.com/k2-fsa/sherpa-onnx/releases/download/asr-models/silero_vad.onnx
-[kws-models]: https://github.com/k2-fsa/sherpa-onnx/releases/tag/kws-models
-[at-models]: https://github.com/k2-fsa/sherpa-onnx/releases/tag/audio-tagging-models
-[sid-models]: https://github.com/k2-fsa/sherpa-onnx/releases/tag/speaker-recongition-models
-[slid-models]: https://github.com/k2-fsa/sherpa-onnx/releases/tag/speaker-recongition-models
-[punct-models]: https://github.com/k2-fsa/sherpa-onnx/releases/tag/punctuation-models
-[speaker-segmentation-models]: https://github.com/k2-fsa/sherpa-onnx/releases/tag/speaker-segmentation-models
-[GigaSpeech]: https://github.com/SpeechColab/GigaSpeech
-[WenetSpeech]: https://github.com/wenet-e2e/WenetSpeech
-[sherpa-onnx-streaming-zipformer-bilingual-zh-en-2023-02-20]: https://github.com/k2-fsa/sherpa-onnx/releases/download/asr-models/sherpa-onnx-streaming-zipformer-bilingual-zh-en-2023-02-20.tar.bz2
-[sherpa-onnx-streaming-zipformer-small-bilingual-zh-en-2023-02-16]: https://github.com/k2-fsa/sherpa-onnx/releases/download/asr-models/sherpa-onnx-streaming-zipformer-small-bilingual-zh-en-2023-02-16.tar.bz2
-[sherpa-onnx-streaming-zipformer-korean-2024-06-16]: https://github.com/k2-fsa/sherpa-onnx/releases/download/asr-models/sherpa-onnx-streaming-zipformer-korean-2024-06-16.tar.bz2
-[sherpa-onnx-streaming-zipformer-zh-14M-2023-02-23]: https://github.com/k2-fsa/sherpa-onnx/releases/download/asr-models/sherpa-onnx-streaming-zipformer-zh-14M-2023-02-23.tar.bz2
-[sherpa-onnx-streaming-zipformer-en-20M-2023-02-17]: https://github.com/k2-fsa/sherpa-onnx/releases/download/asr-models/sherpa-onnx-streaming-zipformer-en-20M-2023-02-17.tar.bz2
-[sherpa-onnx-zipformer-ja-reazonspeech-2024-08-01]: https://github.com/k2-fsa/sherpa-onnx/releases/download/asr-models/sherpa-onnx-zipformer-ja-reazonspeech-2024-08-01.tar.bz2
-[sherpa-onnx-zipformer-ru-2024-09-18]: https://github.com/k2-fsa/sherpa-onnx/releases/download/asr-models/sherpa-onnx-zipformer-ru-2024-09-18.tar.bz2
-[sherpa-onnx-zipformer-korean-2024-06-24]: https://github.com/k2-fsa/sherpa-onnx/releases/download/asr-models/sherpa-onnx-zipformer-korean-2024-06-24.tar.bz2
-[sherpa-onnx-zipformer-thai-2024-06-20]: https://github.com/k2-fsa/sherpa-onnx/releases/download/asr-models/sherpa-onnx-zipformer-thai-2024-06-20.tar.bz2
-[sherpa-onnx-nemo-transducer-giga-am-russian-2024-10-24]: https://github.com/k2-fsa/sherpa-onnx/releases/download/asr-models/sherpa-onnx-nemo-transducer-giga-am-russian-2024-10-24.tar.bz2
-[sherpa-onnx-paraformer-zh-2024-03-09]: https://github.com/k2-fsa/sherpa-onnx/releases/download/asr-models/sherpa-onnx-paraformer-zh-2024-03-09.tar.bz2
-[sherpa-onnx-nemo-ctc-giga-am-russian-2024-10-24]: https://github.com/k2-fsa/sherpa-onnx/releases/download/asr-models/sherpa-onnx-nemo-ctc-giga-am-russian-2024-10-24.tar.bz2
-[sherpa-onnx-telespeech-ctc-int8-zh-2024-06-04]: https://github.com/k2-fsa/sherpa-onnx/releases/download/asr-models/sherpa-onnx-telespeech-ctc-int8-zh-2024-06-04.tar.bz2
-[sherpa-onnx-sense-voice-zh-en-ja-ko-yue-2024-07-17]: https://github.com/k2-fsa/sherpa-onnx/releases/download/asr-models/sherpa-onnx-sense-voice-zh-en-ja-ko-yue-2024-07-17.tar.bz2
-[sherpa-onnx-streaming-zipformer-fr-2023-04-14]: https://github.com/k2-fsa/sherpa-onnx/releases/download/asr-models/sherpa-onnx-streaming-zipformer-fr-2023-04-14.tar.bz2
-[Moonshine tiny]: https://github.com/k2-fsa/sherpa-onnx/releases/download/asr-models/sherpa-onnx-moonshine-tiny-en-int8.tar.bz2
-[NVIDIA Jetson Orin NX]: https://developer.download.nvidia.com/assets/embedded/secure/jetson/orin_nx/docs/Jetson_Orin_NX_DS-10712-001_v0.5.pdf?RCPGu9Q6OVAOv7a7vgtwc9-BLScXRIWq6cSLuditMALECJ_dOj27DgnqAPGVnT2VpiNpQan9SyFy-9zRykR58CokzbXwjSA7Gj819e91AXPrWkGZR3oS1VLxiDEpJa_Y0lr7UT-N4GnXtb8NlUkP4GkCkkF_FQivGPrAucCUywL481GH_WpP_p7ziHU1Wg==&t=eyJscyI6ImdzZW8iLCJsc2QiOiJodHRwczovL3d3dy5nb29nbGUuY29tLmhrLyJ9
-[NVIDIA Jetson Nano B01]: https://www.seeedstudio.com/blog/2020/01/16/new-revision-of-jetson-nano-dev-kit-now-supports-new-jetson-nano-module/
-[speech-enhancement-models]: https://github.com/k2-fsa/sherpa-onnx/releases/tag/speech-enhancement-models
-[source-separation-models]: https://github.com/k2-fsa/sherpa-onnx/releases/tag/source-separation-models
-[RK3588]: https://www.rock-chips.com/uploads/pdf/2022.8.26/192/RK3588%20Brief%20Datasheet.pdf
-[spleeter]: https://github.com/deezer/spleeter
-[UVR]: https://github.com/Anjok07/ultimatevocalremovergui
-[gtcrn]: https://github.com/Xiaobin-Rong/gtcrn
-[tts-url]: https://k2-fsa.github.io/sherpa/onnx/tts/all-in-one.html
-[ss-url]: https://k2-fsa.github.io/sherpa/onnx/source-separation/index.html
-[sd-url]: https://k2-fsa.github.io/sherpa/onnx/speaker-diarization/index.html
-[slid-url]: https://k2-fsa.github.io/sherpa/onnx/spoken-language-identification/index.html
-[at-url]: https://k2-fsa.github.io/sherpa/onnx/audio-tagging/index.html
-[vad-url]: https://k2-fsa.github.io/sherpa/onnx/vad/index.html
-[kws-url]: https://k2-fsa.github.io/sherpa/onnx/kws/index.html
-[punct-url]: https://k2-fsa.github.io/sherpa/onnx/punctuation/index.html
-[se-url]: https://k2-fsa.github.io/sherpa/onnx/speech-enhancement/index.html
-[rknpu-doc]: https://k2-fsa.github.io/sherpa/onnx/rknn/index.html
-[qnn-doc]: https://k2-fsa.github.io/sherpa/onnx/qnn/index.html
-[ascend-doc]: https://k2-fsa.github.io/sherpa/onnx/ascend/index.html
-[axera-npu]: https://axera-tech.com/Skill/166.html
-[SpacemiT-K1]: https://cdn-resource.spacemit.com/file/chip/K1/K1_brief_zh.pdf
-[SpacemiT-K3]: https://cdn-resource.spacemit.com/file/chip/K3/K3_brief_zh.pdf
+The upstream Apache 2.0 license is included in [LICENSE](LICENSE).